# Aayush Bharti — Full Content
> Full-Stack Developer specializing in Next.js, React, TypeScript, and Sanity CMS. I build fast, accessible web apps and help founders ship products that users love.
Website: https://aayushbharti.in
Email: hello@aayushbharti.in
GitHub: https://github.com/aayushbharti
LinkedIn: https://linkedin.com/in/iaayushbharti
---
# About
I'm Aayush Bharti, a proactive full-stack developer passionate about creating dynamic web experiences. From frontend to backend, I thrive on solving complex problems with clean, efficient code. My expertise spans React, Next.js, and Node.js, and I'm always eager to learn more.
---
# Blog Posts
## How to Optimise a Next.js Web App
> Practical techniques to fix your Next.js Lighthouse score — bundle analysis, caching strategies, React Compiler, and the next.config flags nobody talks about.
- Author: Aayush Bharti
- Published: Tue Apr 14 2026 00:00:00 GMT+0000 (Coordinated Universal Time)
- Updated: Wed May 13 2026 00:00:00 GMT+0000 (Coordinated Universal Time)
- Tags: nextjs, performance, react, web-vitals
- Reading time: 15 min
- URL: https://aayushbharti.in/blog/how-to-optimise-a-nextjs-web-app
Your Next.js app scores a 54 on Lighthouse. You shipped it three months ago with a perfect 100, and now there's an analytics SDK, a cookie banner, two icon libraries you imported wrong, and a client component wrapping your entire layout because someone needed `useState` in the header. I've been there — more than once — and the fix is never one silver bullet. It's twenty small decisions compounding in the right direction.
This is every optimisation technique I've used across production Next.js apps, ordered by how quickly you'll see results. No fluff, no "it depends" without telling you what it depends on. Let's fix your score.
## 1. Bundle size — the one that surprises everyone
Before optimising anything, you need to know what you're shipping. Most Next.js apps are 2-3x larger than they need to be, and the culprit is almost never your code (I know, that hurts) — it's your dependencies.
### 1.1 Analyse first, cut second
Run the built-in analyzer (Next.js 16.1+):
```bash title="Terminal"
npx next experimental-analyze
```
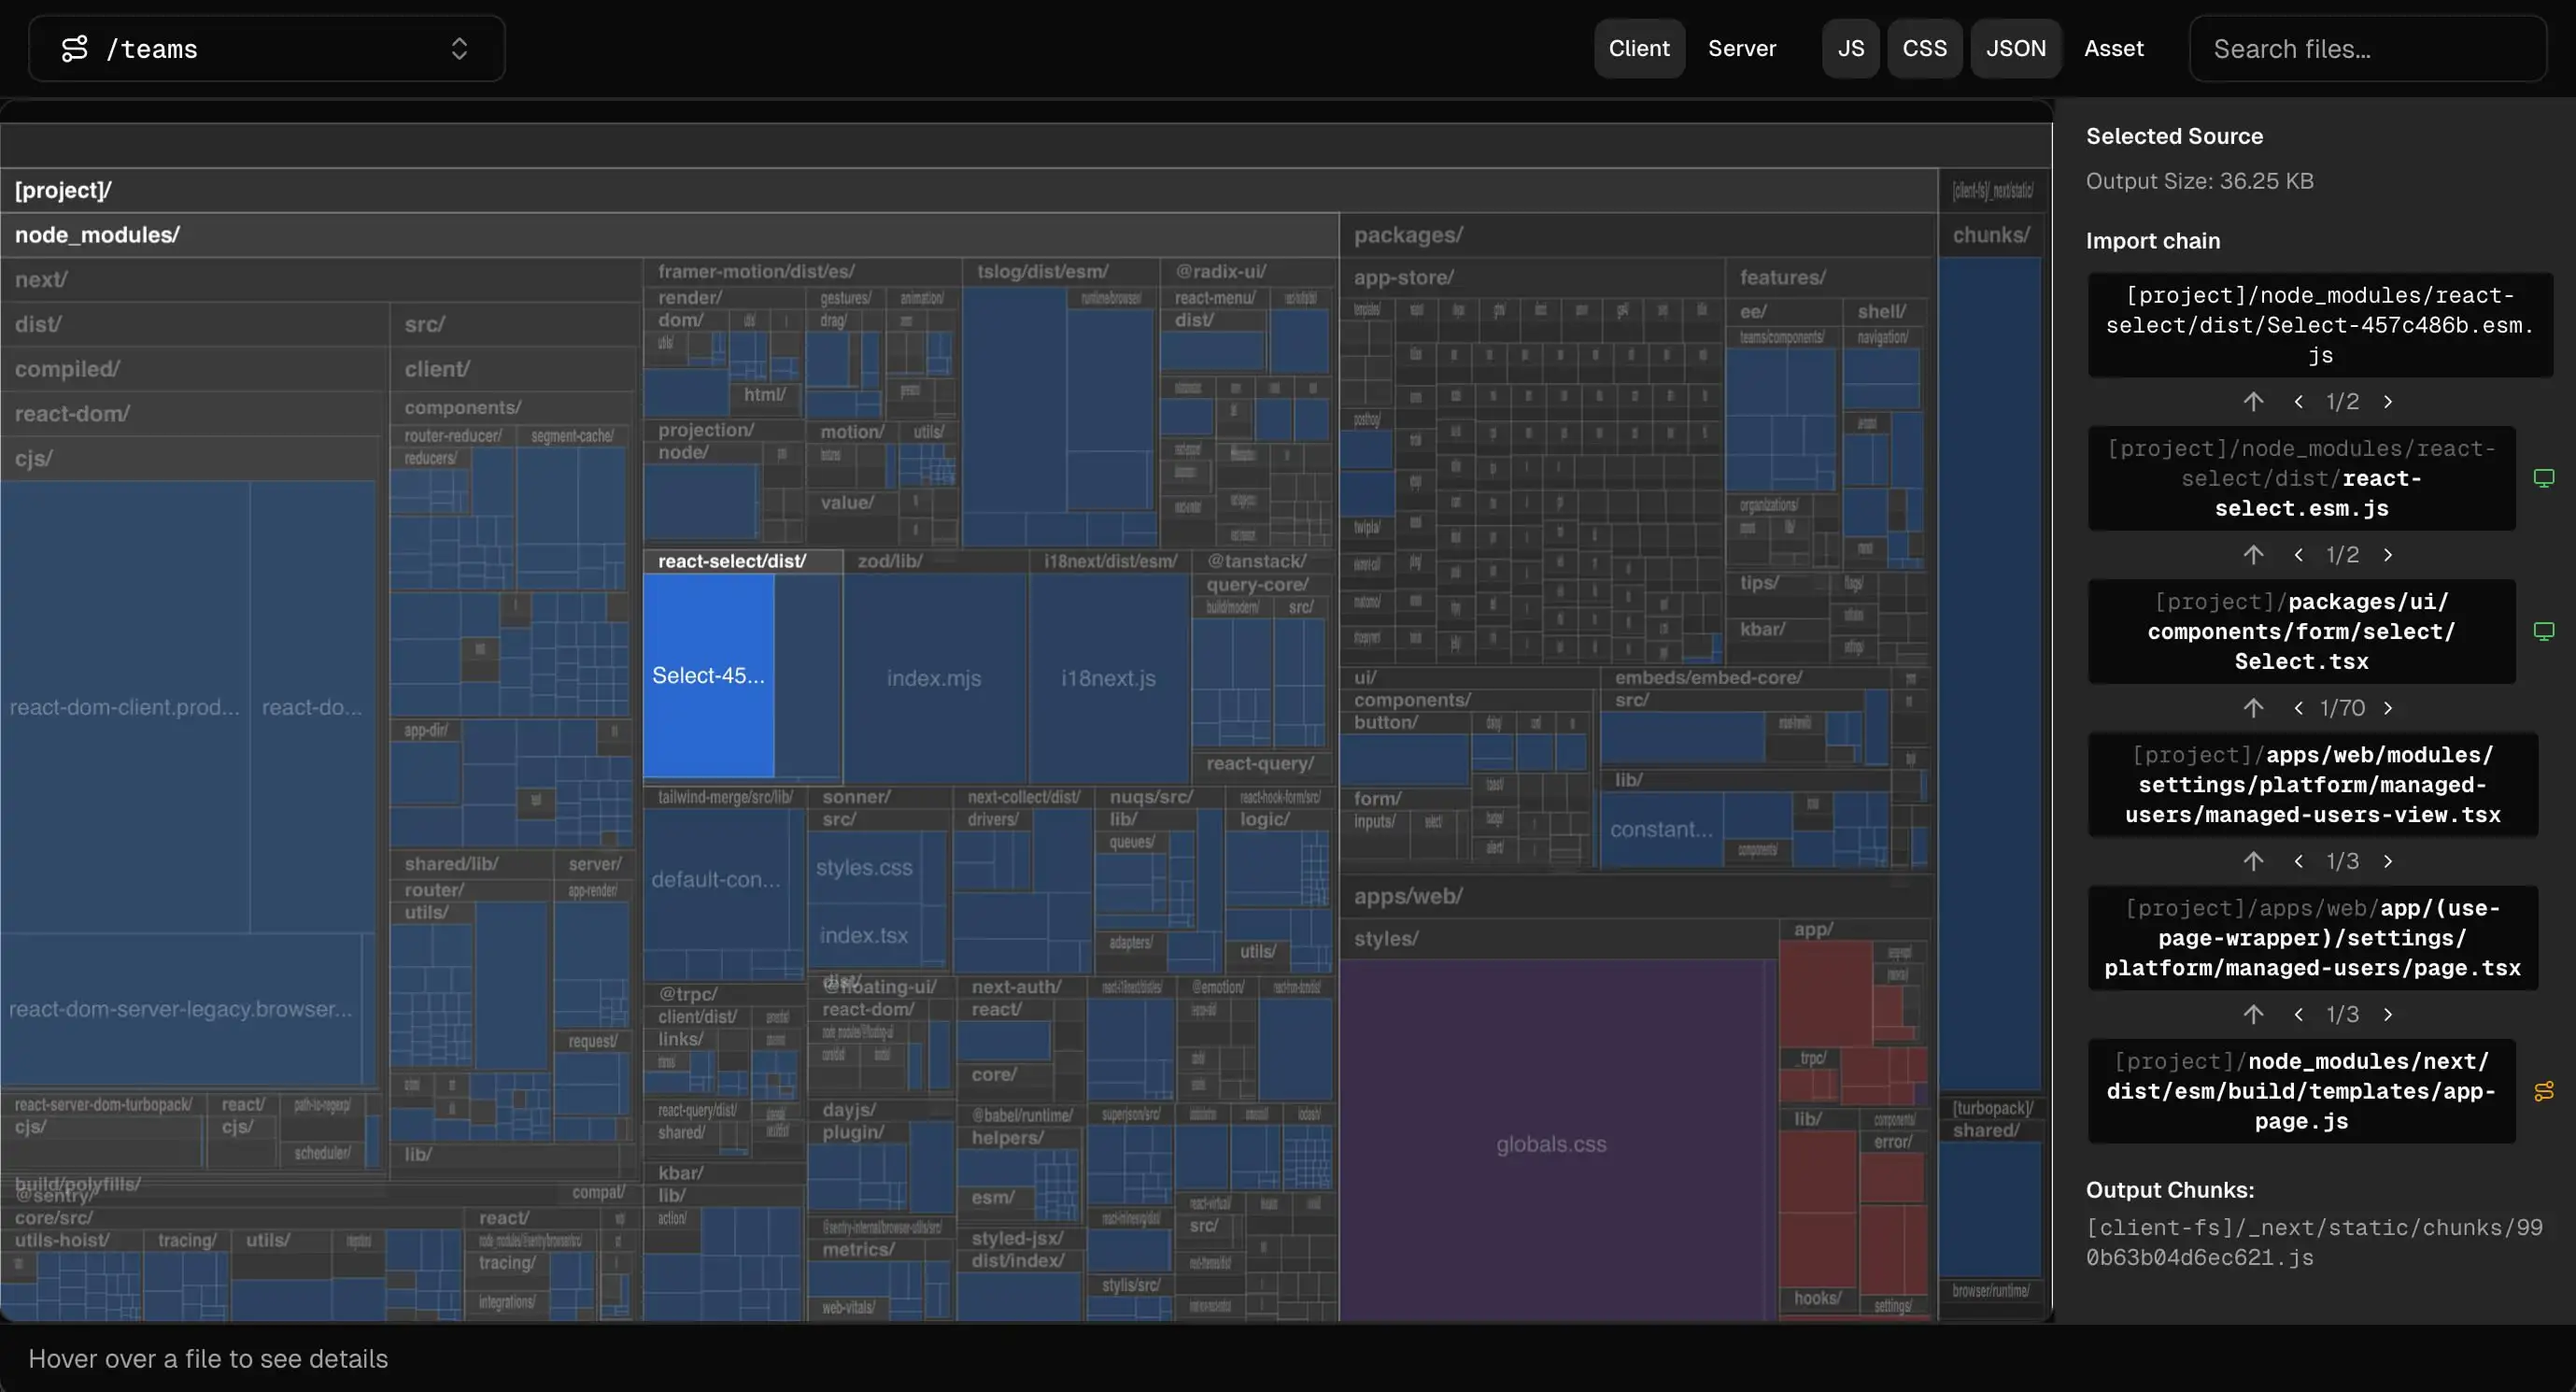
You'll get a treemap showing exactly which packages eat the most space. Look for the usual suspects: `moment.js` (328KB — replace with `date-fns` or the native `Intl` API), full lodash imports, and icon libraries where you imported the entire set instead of individual icons.
### 1.2 The barrel export trap
Some packages export hundreds of modules from a single entry point — icon libraries, utility kits, component frameworks. You import one function and the bundler pulls in everything because it can't tree-shake inside `node_modules`.
Next.js has a fix for this. Add the package to `optimizePackageImports` and it rewrites your barrel imports to direct imports at build time — same developer experience, fraction of the bundle:
```ts title="next.config.ts"
const nextConfig = {
experimental: {
optimizePackageImports: ["@phosphor-icons/react", "recharts"], // [!code highlight]
},
};
```
Many popular libraries (`lodash-es`, `date-fns`, `@mui/material`, and [others](https://nextjs.org/docs/app/api-reference/config/next-config-js/optimizePackageImports)) are already optimised by default — check the list before adding them manually. I added two packages on this site and shaved ~180KB off the client bundle with zero code changes.
### 1.3 Server Components — stop shipping JS you don't need
Every component in App Router is a Server Component by default — it ships zero JS to the browser. The mistake I see most often: marking an entire page as `"use client"` because one small piece needs interactivity.
```tsx title="components/blog-post.tsx"
"use client"; // Ships the entire page as JS // [!code --]
export default function BlogPost({ post }) {
const [liked, setLiked] = useState(false); // State forces everything client-side // [!code --]
return (
{post.title}
{post.content}
{/* Static content — no reason to ship as JS */}
// [!code --]
{/* Only this tiny piece ships JS */} // [!code ++]
);
}
```
Push `"use client"` as deep into the component tree as possible. The boundary should wrap the smallest interactive surface — a button, a form, a search input — not a page, not a layout.
> **Common RSC pitfall**
>
> Passing a Server Component as `children` to a Client Component? It still runs on the server. This is how you compose interactive wrappers around static content without shipping the static content as JS.
> **Quick wins for bundle size**
>
> - Replace `moment` with `date-fns` or native `Intl.DateTimeFormat`
> - Use specific imports for icon libraries, never `import * from`
> - Audit with the bundle analyzer after every major dependency addition
> - Target under 500KB total JS per page — 1500KB is the absolute ceiling
## 2. Core Web Vitals and optimising FCP/LCP
Google uses four Core Web Vitals to rank your site. Here's what they actually mean and what "good" looks like:
| Metric | What it measures | Good | Needs work | Poor |
|---|---|---|---|---|
| **FCP** (First Contentful Paint) | Time until first text/image appears | < 1.8s | 1.8 - 3.0s | > 3.0s |
| **LCP** (Largest Contentful Paint) | Time until the largest visible element renders | < 2.5s | 2.5 - 4.0s | > 4.0s |
| **INP** (Interaction to Next Paint) | Delay between user interaction and visual response | < 200ms | 200 - 500ms | > 500ms |
| **CLS** (Cumulative Layout Shift) | How much the page layout shifts unexpectedly | < 0.1 | 0.1 - 0.25 | > 0.25 |
INP replaced FID (First Input Delay) in March 2024 — if you're still reading articles that reference FID, they're outdated.
### 2.1 Measure before you optimise
Run [PageSpeed Insights](https://pagespeed.web.dev/) on your production URL — not localhost, not a preview deployment. That's what Google actually measures.
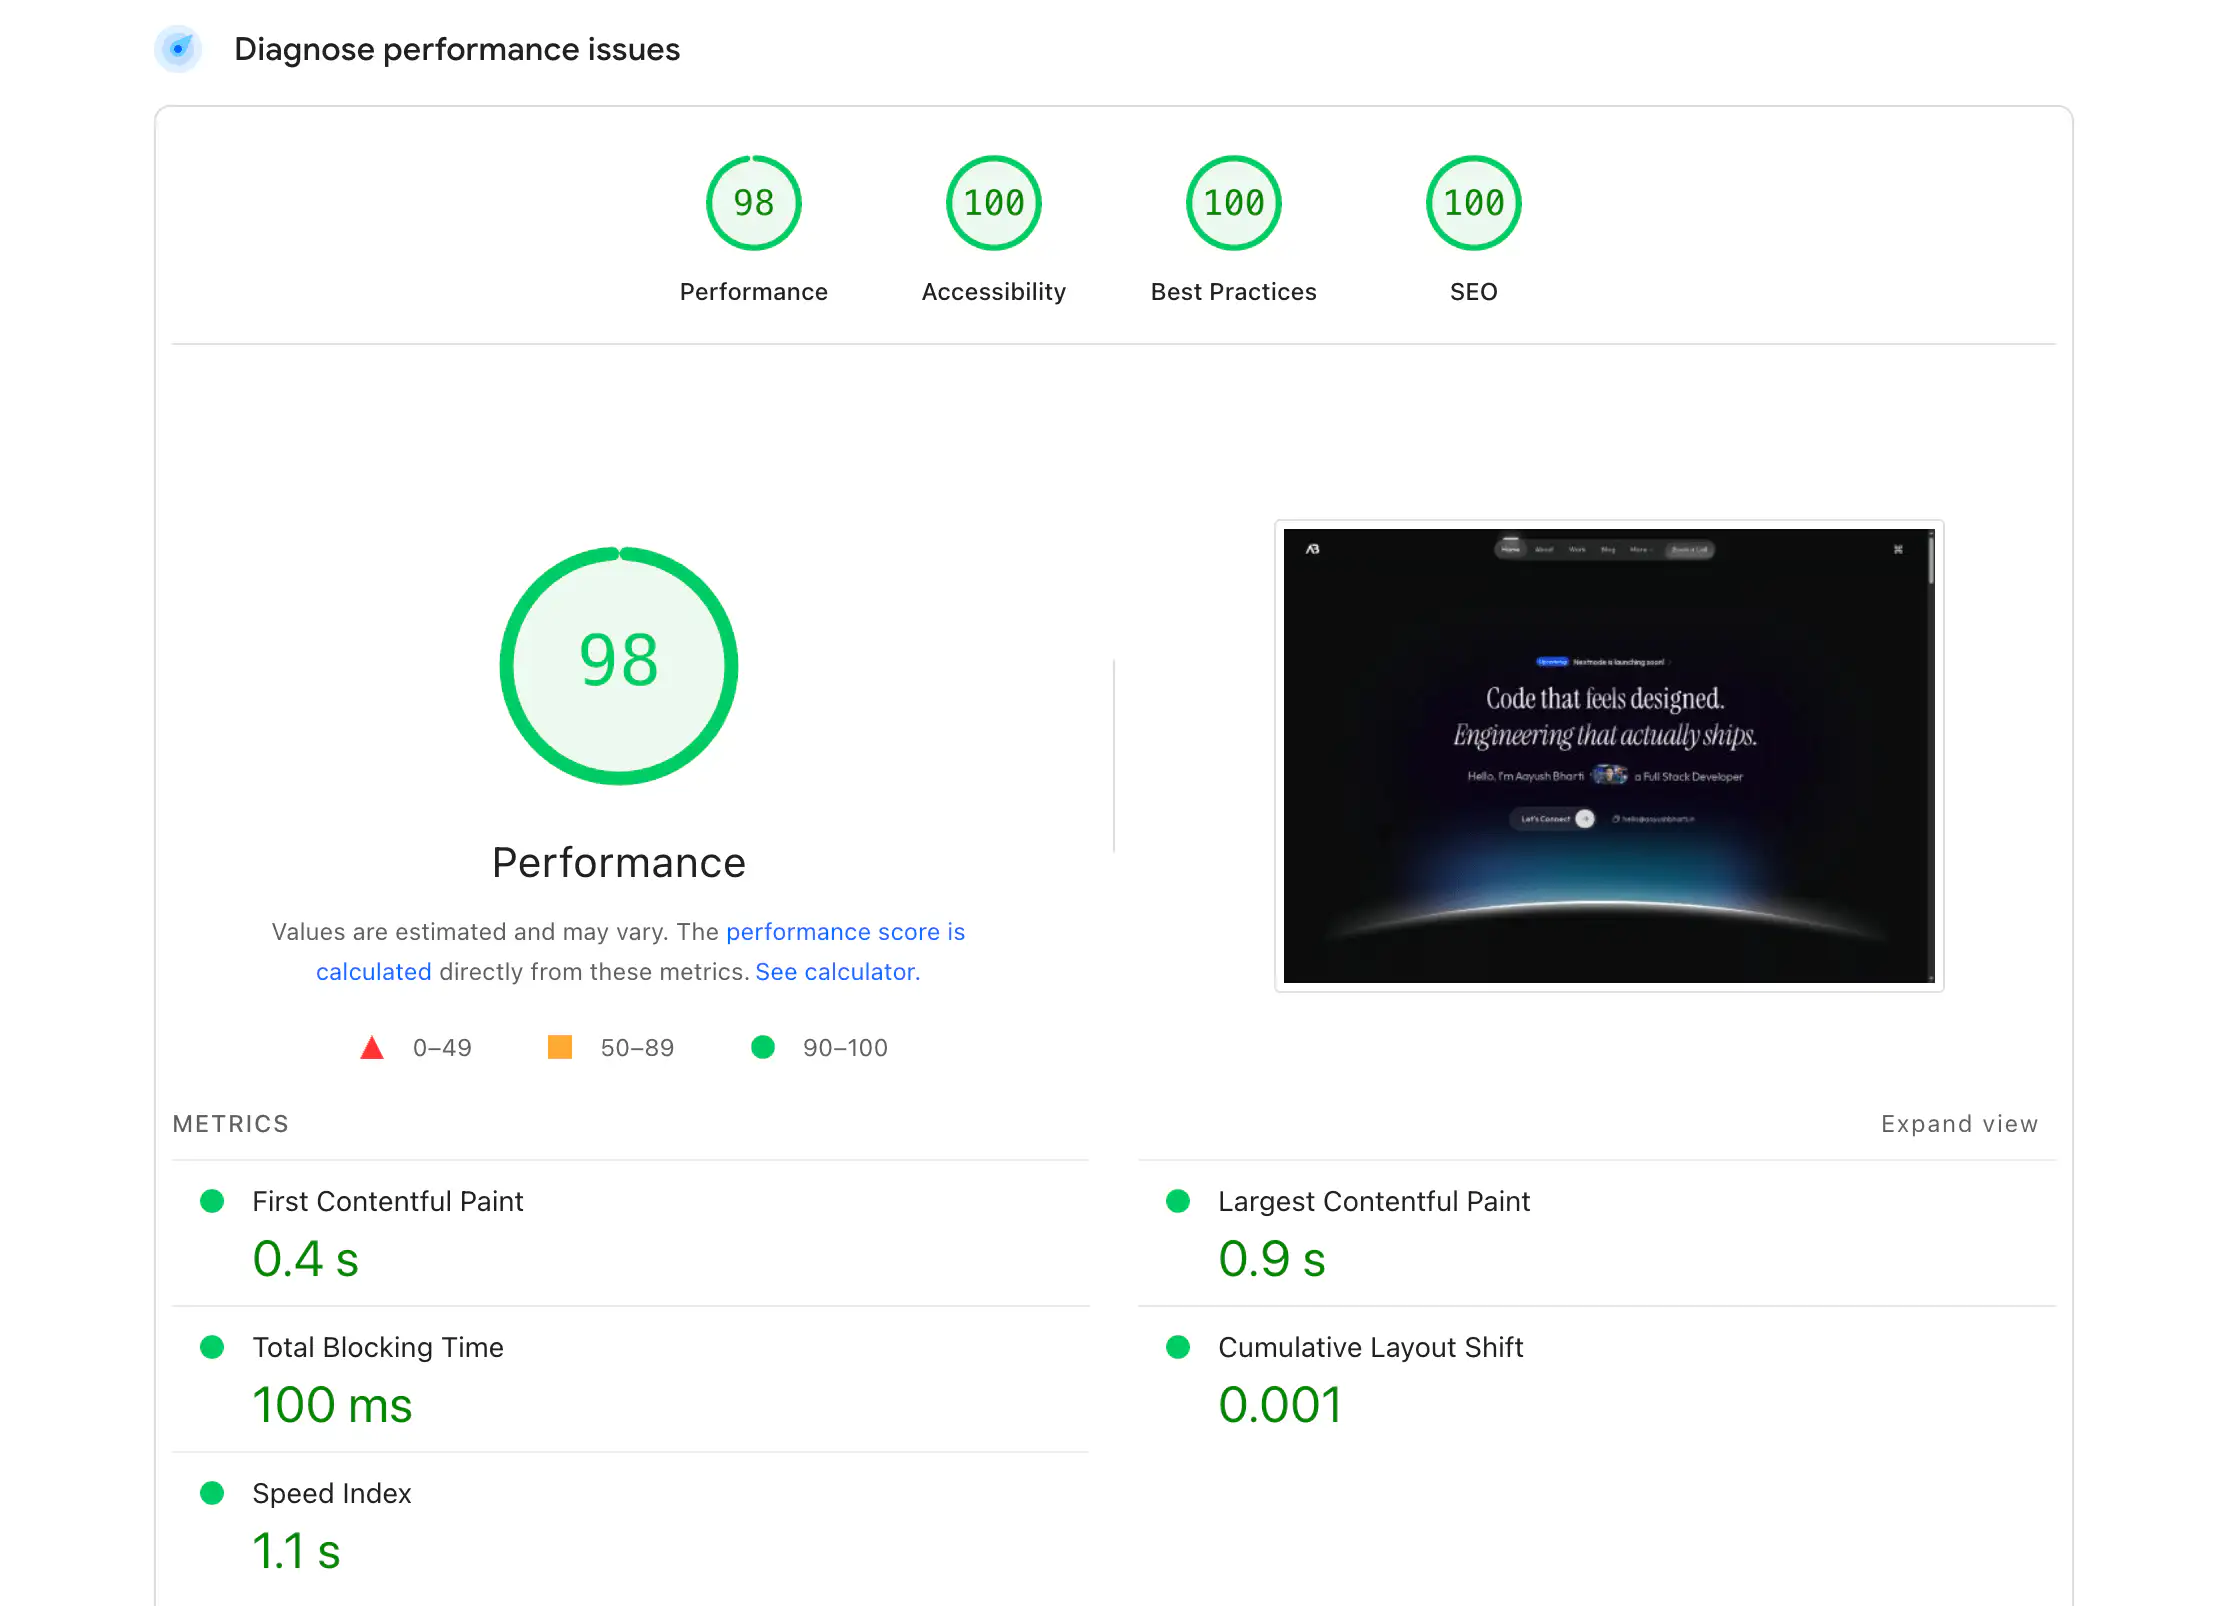
For real-user data, check the [Chrome User Experience Report (CrUX)](https://developer.chrome.com/docs/crux/) — this is what Google uses for search rankings. For continuous monitoring, add [`@vercel/speed-insights`](https://vercel.com/docs/speed-insights) to your layout.
### 2.2 Images — the biggest LCP lever
`next/image` handles format conversion (WebP/AVIF), responsive sizing, and lazy loading automatically. Three things most people get wrong:
**1. Mark the hero image as `priority`.** Your LCP element is usually the largest above-the-fold image. By default, `next/image` lazy loads everything — the `priority` prop disables that and adds a `` to the document head.
```tsx title="components/hero.tsx"
```
**2. Use blur placeholders.** LQIP (Low Quality Image Placeholders) show a blurred preview instantly while the full image loads. Add `placeholder="blur"` with a `blurDataURL`.
**3. Don't lazy-load above-the-fold images.** If it's visible without scrolling, add `priority` or `loading="eager"`.
### 2.3 Fonts — zero layout shift
`next/font` self-hosts fonts and eliminates external network requests. Use `display: "swap"` so text renders immediately with a fallback, and `adjustFontFallback` (enabled by default) calculates CSS overrides so the font swap causes zero CLS.
```tsx title="app/layout.tsx"
import { Inter } from "next/font/google";
const inter = Inter({ subsets: ["latin"], display: "swap" }); // [!code highlight]
export default function RootLayout({ children }) {
return (
{children}
);
}
```
### 2.4 Defer third-party scripts
Analytics, chat widgets, cookie banners — they all want to load during your critical rendering path. Push them out with `next/script`:
```tsx title="app/layout.tsx"
import Script from "next/script";
```
| Strategy | When it loads | Use for |
|---|---|---|
| `beforeInteractive` | Before hydration | Critical A/B testing, bot detection |
| `afterInteractive` | After some hydration (default) | Analytics, tag managers |
| `lazyOnload` | After page is idle | Chat widgets, social embeds, cookie banners |
For Google services, use [`@next/third-parties`](https://nextjs.org/docs/app/guides/third-party-libraries) — it loads GA, Maps, and YouTube embeds with optimised defaults out of the box.
Add `preconnect` hints for third-party origins — each one saves 100-500ms of DNS + TCP + TLS handshake time:
```tsx title="app/layout.tsx"
```
## 3. Rendering strategies
Choosing the right rendering strategy has a direct impact on TTFB, FCP, and LCP.
| Strategy | How it works | TTFB | Use when |
|---|---|---|---|
| **SSG** | HTML generated at build time, served from CDN | Fastest | Landing pages, docs, blogs — content rarely changes |
| **ISR** | Static + revalidates at a fixed interval | Fast | Product listings, content that changes every few minutes/hours |
| **SSR** | HTML generated per request | Depends on backend | SEO-critical pages with real-time or personalised data |
| **CSR** | Renders entirely in browser | N/A | Dashboards, internal tools — SEO doesn't matter |
```mermaid
graph LR
A{Needs SEO?} -->|No| CSR["CSR\nClient-Side"]
A -->|Yes| B{Per-request\ndata?}
B -->|Yes| SSR["SSR\nServer-Side"]
B -->|No| C{Updates\nperiodically?}
C -->|Yes| ISR["ISR\nIncremental"]
C -->|No| SSG["SSG\nStatic"]
```
Start with SSG. Move to ISR if data needs freshness. Move to SSR only if data needs per-request accuracy. CSR is a last resort. If you're on Next.js 16+, look at Partial Prerendering (PPR) — it serves a static shell instantly and streams dynamic sections, combining the best of SSG and SSR in a single page.
## 4. Code splitting and dynamic imports
Next.js splits code at the route level automatically — each page only loads the JavaScript it needs. But heavy components within a page still land in that page's bundle unless you split them manually (the bundler is helpful, not psychic).
Use `next/dynamic` for components that are heavy, below the fold, or client-only:
```tsx title="components/dashboard-charts.tsx"
"use client"; // ssr: false only works in Client Components
import dynamic from "next/dynamic";
const Chart = dynamic(() => import("@/components/chart"), {
ssr: false, // Skip server render — this uses browser APIs // [!code highlight]
loading: () => ,
});
```
**Use dynamic imports for:** heavy client libraries (charts, editors), browser-only APIs (`window`, `document`), below-the-fold content most users never scroll to.
**Don't use them for:** small shared components, above-the-fold UI, layout components. Every dynamic import creates a separate network request — splitting ten small components into ten chunks is worse than one bundle.
## 5. Data fetching and caching
Slow data fetching is the quiet one that bites you. Your rendering strategy doesn't matter if you're waterfalling three sequential API calls before the page can render.
### 5.1 Parallel data fetching
The most common mistake: sequential `await`s when the calls don't depend on each other.
```ts title="Don't do this — sequential waterfall"
const user = await getUser(); // 200ms
const posts = await getPosts(); // 300ms
const comments = await getComments(); // 150ms
// Total: 650ms — each waits for the previous one
```
```ts title="Do this — parallel fetching"
const [user, posts, comments] = await Promise.all([ // [!code highlight]
getUser(), // 200ms ─┐
getPosts(), // 300ms ─┤ All start simultaneously
getComments(), // 150ms ─┘
]);
// Total: 300ms — limited by the slowest call
```
54% faster from one line. No library, no config — `Promise.all` and done.
### 5.2 Request deduplication with `cache()`
React's `cache()` deduplicates identical requests within a single render pass. If three components all call `getUser()`, it executes once.
```ts title="lib/data.ts"
import { cache } from "react";
export const getUser = cache(async (id: string) => { // [!code highlight]
const res = await fetch(`/api/users/${id}`);
return res.json();
});
```
### 5.3 The `"use cache"` directive
This is the big one that almost no blog covers yet. `"use cache"` is a declarative caching directive — first introduced experimentally in Next.js 15 and enabled via Cache Components in Next.js 16. It replaces the old `fetch()` cache options and `unstable_cache`.
First, enable it in your config:
```ts title="next.config.ts"
const nextConfig = {
cacheComponents: true, // [!code highlight]
};
```
Then use it at the page level, layout level, or individual functions:
```tsx title="app/blog/page.tsx"
"use cache";
import { cacheLife } from "next/cache";
export default async function BlogPage() {
cacheLife("hours"); // Cache this page's output for hours // [!code highlight]
const posts = await getAllPosts();
return ;
}
```
The built-in cache profiles:
| Profile | Stale | Revalidate | Expire |
|---|---|---|---|
| `"default"` | 5min | 15min | never |
| `"seconds"` | 30s | 1s | 1min |
| `"minutes"` | 5min | 1min | 1hr |
| `"hours"` | 5min | 1hr | 1 day |
| `"days"` | 5min | 1 day | 1 week |
| `"weeks"` | 5min | 1 week | 30 days |
| `"max"` | 5min | 30 days | 1 year |
If you don't call `cacheLife()` at all, the `default` profile is used. For on-demand revalidation, pair it with `cacheTag()` and call `revalidateTag()` from an API route or Server Action. This replaces the old route segment configs (`revalidate`, `dynamic`, `fetchCache`) — don't mix both models.
## 6. Streaming and Suspense
Traditional SSR waits for the slowest data source before sending anything. If your content loads in 100ms but comments take 2 seconds, the user stares at a blank screen for 2 seconds.
Streaming fixes this — the server sends fast parts immediately and streams slow parts as they resolve:
```tsx title="app/blog/[slug]/page.tsx"
import { Suspense } from "react";
export default async function BlogPost({ params }) {
const { slug } = await params;
const post = await getPost(slug); // Fast — 50ms
return (
{post.title}
{post.content}
}> // [!code highlight]
{/* Streams in when ready — 800ms */}
);
}
```
Place Suspense boundaries around non-critical data fetchers, below-the-fold sections, and personalised content. Don't wrap above-the-fold content — a loading flash there hurts perceived performance more than it helps.
For page-level streaming, you can also use a `loading.tsx` file — Next.js wraps the page in a Suspense boundary for you automatically:
```tsx title="app/dashboard/loading.tsx"
export default function Loading() {
return ;
}
```
This is the simplest way to get streaming — one file, zero Suspense imports, instant loading states for entire route segments.
## 7. React Compiler
Here's a technique zero performance articles talk about (I checked): stop memoising things manually.
React Compiler analyses your components at build time and automatically inserts `useMemo`, `useCallback`, and `React.memo` where they'll actually help — not where you think they'll help, but where static analysis proves it.
First, install the Babel plugin:
```bash title="Terminal"
pnpm add -D babel-plugin-react-compiler
```
Then enable it in your config — note this is a **top-level** option, not inside `experimental`:
```ts title="next.config.ts"
const nextConfig = {
reactCompiler: true, // [!code highlight]
};
```
In most cases, you can remove your manual `useMemo`/`useCallback`/`React.memo` calls — the compiler analyses the actual dependency graph at build time instead of relying on you listing deps correctly in an array. If a specific component needs to opt out, use the `"use no memo"` directive. Fewer unnecessary re-renders means better INP.
## 8. next.config power flags
These are the flags I run in production that most developers don't know exist. (Free performance. No code changes. You're welcome.)
### 8.1 `inlineCss`
Inlines CSS directly into HTML instead of serving it as separate files. Eliminates render-blocking CSS requests.
```ts title="next.config.ts"
const nextConfig = {
experimental: {
inlineCss: true, // [!code highlight]
},
};
```
One fewer network round-trip per page load. Only works in production builds. The tradeoff: inlined CSS can't be cached separately, so returning visitors re-download styles — best for first-visit-heavy sites like landing pages and blogs.
### 8.2 `staleTimes`
Controls how long the client-side router caches visited pages. By default, dynamic pages are cached for 0 seconds (re-fetched on every navigation) and static pages for 5 minutes.
```ts title="next.config.ts"
const nextConfig = {
experimental: {
staleTimes: {
dynamic: 30, // Cache dynamic pages for 30s on client // [!code highlight]
static: 180, // Cache static pages for 3 min on client
},
},
};
```
This means navigating back to a previously visited page is instant for 30 seconds instead of triggering a new server request. Big win for apps with frequent back-and-forth navigation.
### 8.3 `serverExternalPackages`
Some Node.js packages break when bundled for Server Components — native bindings, packages that use `__dirname`, or packages with side effects during import. This flag tells Next.js to skip bundling and use native `require()`.
```ts title="next.config.ts"
const nextConfig = {
serverExternalPackages: ["puppeteer", "canvas"],
};
```
Many common packages (`sharp`, `bcrypt`, `prisma`, and others) are already excluded by default — you only need this for packages not on the [automatic opt-out list](https://nextjs.org/docs/app/api-reference/config/next-config-js/serverExternalPackages).
### 8.4 `removeConsole`
Strip `console.log` statements from production builds. Less noise, slightly smaller bundles.
```ts title="next.config.ts"
const nextConfig = {
compiler: {
removeConsole: {
exclude: ["error"], // Keep console.error for debugging // [!code highlight]
},
},
};
```
## 9. Production checklist
Before you ship, run through this. I've ordered by impact — fix the high-priority items first.
### 9.1 High Priority
- Page JS under 500KB (absolute max 1500KB) — Directly impacts FCP, LCP, and INP
- priority on LCP image — Prevents lazy-loading the most important image
- No sequential data waterfalls — Promise.all for independent fetches
- use client only on leaf components — Every client component ships JS to the browser
- Non-blocking third-party scripts (lazyOnload) — Keeps scripts out of the critical path
- HTTPS enabled — Required for HTTP/2, required for Google ranking
- TTFB under 1.3 seconds — Server response time caps everything downstream
### 9.2 Medium Priority
- next/image for all images with width/height — Prevents CLS, enables format optimisation
- next/font with display: swap — Eliminates font-related CLS
- CDN for images and static assets — Reduces TTFB by serving from edge
- Blur placeholders on content images — Improves perceived loading speed
- Suspense boundaries around slow data — Unblocks fast content from slow dependencies
- Dependencies audited and up to date — Newer versions often ship smaller bundles
- preconnect for third-party origins — Saves 100-500ms per external domain
### 9.3 Low Priority
- WOFF2 font format — Smallest font file size available
- inlineCss enabled in production — Eliminates one render-blocking request
- removeConsole in production — Marginal bundle reduction, cleaner runtime
- Vector images (SVG) over bitmaps where possible — Infinitely scalable, usually smaller
- HTTP cache headers on static assets — Cache-Control: immutable for /_next/static/
- staleTimes tuned for your navigation patterns — Instant back-navigation for visited pages
---
Here's the thing nobody tells you about performance work: hitting a 100 on Lighthouse is easy. Staying there is the actual job.
Every feature you ship, every dependency you add, every "just this one client component" — they're all small withdrawals from a budget your users never agreed to. The sites that stay fast aren't the ones that optimised once. They're the ones that made performance a constraint, not a cleanup task.
Add `@vercel/speed-insights` to your layout. Set a bundle budget in CI. Make the number visible to your team every week. When someone asks "can we add this 200KB carousel library?" — the dashboard answers for you.
The best Lighthouse score is the one you never have to fix twice.
## Frequently asked questions
### What are good Core Web Vitals scores for a Next.js site?
Aim for the good thresholds: LCP under 2.5s, FCP under 1.8s, INP under 200ms, and CLS under 0.1. INP replaced FID in March 2024. Measure on your production URL with PageSpeed Insights, since Google ranks on real-user CrUX data rather than localhost.
### How do I reduce my Next.js bundle size?
Run the built-in analyzer (npx next experimental-analyze on 16.1+) to see which dependencies dominate, then add barrel-heavy packages like icon and utility libraries to optimizePackageImports, swap moment for date-fns or the native Intl API, and keep use client on leaf components. Target under 500KB of JS per page, with 1500KB as the absolute ceiling.
### Why is my entire Next.js page shipping as client-side JavaScript?
A single use client at the top of a page or layout forces the whole subtree to ship as JS. In the App Router every component is a Server Component by default and ships zero JS, so push the use client boundary as deep as possible, around the button or form that needs interactivity rather than the page. Server Components passed as children to a Client Component still render on the server.
### What is the use cache directive in Next.js?
use cache is a declarative caching directive enabled with cacheComponents: true in Next.js 16 (experimental in 15). Add it to a page, layout, or function and set the duration with cacheLife(), using built-in profiles from seconds to max. It replaces fetch cache options, unstable_cache, and the old route-segment configs, so don't mix the two models.
### How do I improve LCP in a Next.js app?
Your LCP element is usually the largest above-the-fold image, so give it next/image with the priority prop, which disables lazy loading and preloads it. Never lazy-load above-the-fold images, add a blur placeholder for an instant preview, and self-host fonts with next/font and display swap to avoid render-blocking requests and layout shift.
### How do I fix slow data fetching in Next.js?
Replace sequential awaits with Promise.all when the requests don't depend on each other: three sequential calls totalling 650ms drop to the slowest one at 300ms, about 54% faster from one line. Wrap repeated requests in React cache() to dedupe them within a render, and stream slow, non-critical sections behind Suspense so fast content isn't blocked.
---
## Every Tool in My Terminal-First Dev Setup
> Neovim, Wezterm, Tmux, and the rest — what survived two years of daily use and why I picked each one over the obvious alternatives.
- Author: Aayush Bharti
- Published: Sun Oct 19 2025 00:00:00 GMT+0000 (Coordinated Universal Time)
- Updated: Sat Feb 21 2026 00:00:00 GMT+0000 (Coordinated Universal Time)
- Tags: developer-tools, terminal, neovim, workflow
- Reading time: 12 min
- URL: https://aayushbharti.in/blog/terminal-first-dev-setup
I switched to a terminal-first workflow two years ago and never looked back. The trigger was embarrassingly mundane: VS Code hit 2.4GB of RAM during a Next.js debugging session while I had Chrome DevTools open, and my laptop froze for thirty seconds mid-demo. That same week, I watched a coworker navigate a monorepo in Neovim faster than I could open the file picker in VS Code.
I felt slow. Not "I should optimize this" slow — "I'm fighting my own tools" slow. So I committed to replacing every GUI developer tool with a terminal-native equivalent and gave myself three months to get productive. Everything in this list survived a regular purge — if a tool doesn't make me measurably faster, it doesn't make the cut. Here's what stayed.
## The core four: editor, terminal, shell, multiplexer
These are load-bearing walls. Swap out anything else and the system still works. Remove one of these and the whole workflow collapses.
### Neovim
[Neovim](https://github.com/neovim/neovim) is the center of gravity. I moved from VS Code because I was tired of Electron eating memory and the constant extension update churn breaking my setup every few weeks. With native LSP support and Treesitter for syntax highlighting, I get the same intelligence features — autocomplete, go-to-definition, inline diagnostics — but startup takes 40ms instead of four seconds.
The real unlock was modal editing. Once you internalize that `ciw` replaces a word and `dd` deletes a line without reaching for the mouse, you stop thinking about text manipulation and start thinking about code. I use [lazy.nvim](https://github.com/folke/lazy.nvim) for plugin management with about 35 plugins — telescope for fuzzy finding, nvim-cmp for completion, and conform.nvim for formatting on save.
The honest limitation: the learning curve is brutal for the first two weeks. You will be slower. You will want to quit. That investment in [learning your tools deeply](/blog/what-i-wish-i-knew-before-learning-to-code) pays compound interest, but nobody tells you how bad week one feels.
### Wezterm
[Wezterm](https://github.com/wez/wezterm) is a GPU-accelerated terminal emulator configured entirely in Lua. I tried Kitty first — solid performance, terrible config syntax. Alacritty flickered on Wayland and had no tab support. Wezterm nails both. The killer feature is scriptable keybindings: I have a Lua function that opens a new tab, `cd`s into a project directory, and attaches the matching Tmux session in one keystroke. The config is a real programming language, not YAML or TOML, so conditionals and loops work naturally.
```lua title="~/.config/wezterm/wezterm.lua"
local wezterm = require("wezterm")
local config = wezterm.config_builder()
config.font = wezterm.font("JetBrains Mono", { weight = "Medium" })
config.font_size = 13.5
config.window_background_opacity = 0.95
config.hide_tab_bar_if_only_one_tab = true
config.window_padding = { left = 8, right = 8, top = 8, bottom = 8 }
-- quick project switcher: Ctrl+Shift+P opens FZF in a new tab
config.keys = {
{
key = "p",
mods = "CTRL|SHIFT",
action = wezterm.action.SpawnCommandInNewTab({
args = { "bash", "-c", "cd $(find ~/Developer -maxdepth 2 -type d | fzf) && exec zsh" },
}),
},
}
return config
```
One annoyance: Wezterm's multiplexer mode is half-baked compared to Tmux. I stopped trying to replace Tmux with it and let each tool do what it's best at.
### ZSH + Oh My Zsh
[ZSH](https://github.com/ohmyzsh/ohmyzsh) with Oh My Zsh is the shell layer. Bash's autocomplete is embarrassing in 2025 — no inline suggestions, no syntax highlighting as you type, no smart history search. ZSH's plugin ecosystem fixes all of that.
I run three plugins that matter: `zsh-autosuggestions` (ghost-text completion from your history), `zsh-syntax-highlighting` (red text when a command doesn't exist, green when it does), and `git` (aliases like `gco` for `git checkout`). The rest of Oh My Zsh I could take or leave. My `.zshrc` is 80 lines and loads in under 200ms — if yours takes longer, audit your plugins.
### Tmux
[Tmux](https://github.com/tmux/tmux) handles session persistence and workspace organization. When my SSH connection drops or I close my laptop mid-debug session, Tmux keeps every pane, every running process, every scroll position alive. I tried Zellij for the modern UX and floating panes, but it crashed twice during production incident debugging — the one time you absolutely need your multiplexer to be rock solid. Tmux is boring and that's the point.
I have three persistent sessions: `work`, `personal`, and `scratch`. Prefix key is rebound to `Ctrl+a` (closer to home row than the default `Ctrl+b`), and I use `tmux-resurrect` to survive full system reboots.
```bash title="~/.tmux.conf"
set -g prefix C-a
unbind C-b
bind C-a send-prefix
set -g mouse on
setw -g mode-keys vi
set -g base-index 1
# session persistence across reboots
set -g @plugin 'tmux-plugins/tmux-resurrect'
set -g @plugin 'tmux-plugins/tmux-continuum'
set -g @continuum-restore 'on'
```
The only complaint is that Tmux's copy mode keybindings are arcane until you configure vi-mode — but once you do, selecting and yanking text feels like Neovim.
## Productivity and utilities
These sit between the core tools and fill the gaps. Each one replaced a slower workflow I didn't realize was slow until I timed it.
### FZF
[FZF](https://github.com/junegunn/fzf) is the single most impactful tool in this entire list. It's a general-purpose fuzzy finder that plugs into everything: `Ctrl+T` for file navigation, `Ctrl+R` for command history search, and inside Neovim via Telescope for project-wide file finding.
The speed difference is visceral — instead of `cd`-ing through four nested directories, I hit a keybind, type three characters, and I'm there. Once you muscle-memory fuzzy finding, navigating with `ls` and `cd` feels like using a flip phone after a smartphone.
FZF's `--preview` flag with bat gives me file previews inline, so I can confirm I'm opening the right file before committing to it. I set these as defaults so every FZF invocation gets previews for free:
```bash title="~/.zshrc"
export FZF_DEFAULT_OPTS="--height 40% --layout=reverse --border"
export FZF_CTRL_T_OPTS="--preview 'bat --color=always --line-range=:50 {}'"
export FZF_ALT_C_OPTS="--preview 'eza --tree --level=2 --icons {}'"
```
> FZF doesn't replace one tool. It replaces the *concept* of navigating to things manually. That mental shift is worth more than any individual config tweak.
### Lazygit
[Lazygit](https://github.com/jesseduffield/lazygit) is a TUI for Git that makes interactive rebasing, conflict resolution, and cherry-picks tolerable. The raw Git CLI is powerful but punishing for complex operations — staging individual hunks requires remembering `git add -p` flags, interactive rebase means editing a file in your `$EDITOR`, and merge conflicts are a wall of angle brackets.
Lazygit gives me a split view: staged changes on one side, diff on the other, keybinds for every operation. I do simple commits from the command line and reach for Lazygit the moment anything gets interactive. The staging interface alone saves me five minutes per session on days with heavy Git work.
### Bat and Btop++
[Bat](https://github.com/sharkdp/bat) replaces `cat` with syntax highlighting, line numbers, and git diff markers. I aliased `cat` to `bat` globally and forgot about it — inspecting a `package.json` or skimming a config file now gives me highlighted output for free. [Btop++](https://github.com/aristocratos/btop) replaced `htop` for process monitoring. The GPU monitoring panel saved me during Three.js debugging when I couldn't figure out why my discrete GPU wasn't activating. Spotted the issue in ten seconds with Btop's GPU utilization graph. Both tools are zero-config improvements to built-in commands.
### Better Commit
[Better Commit](https://github.com/Everduin94/better-commits) enforces conventional commits without me memorizing the format every time. I tried Commitizen and found it slower with more prompts — Better Commit asks fewer questions and gets out of the way faster. If you're working on a project with CI that validates commit messages (and you should be), this eliminates the "oops, wrong prefix" cycle.
## Shell replacements that compound daily
These are modern rewrites of Unix coreutils. Individually, each saves a few seconds. Collectively, they reshape how you interact with the filesystem. Small friction reductions compound — I estimated these save me 15-20 minutes per day across hundreds of small interactions.
**[eza](https://github.com/eza-community/eza)** replaces `ls` with git-aware file listings, icons, and tree views built in. `eza -la --git` shows me file permissions, sizes, and git status in one shot — information that previously required piping `ls` through multiple commands. I aliased `ls` to `eza` and `tree` to `eza --tree`, so the muscle memory stays the same but the output is categorically better.
```bash title="~/.zshrc"
alias ls="eza --icons"
alias ll="eza -la --icons --git"
alias tree="eza --tree --icons --level=3"
```
**[zoxide](https://github.com/ajeetdsouza/zoxide)** replaces `cd` with frecency-based directory jumping. It learns your habits — after a week of normal use, I stopped typing full paths entirely. The lookup is instant and gets smarter the more you use it.
```bash title="Terminal"
# zoxide learns paths automatically as you navigate
cd ~/Developer/aayush/next-portfolio
# later — from anywhere on the system
z portfolio # jumps to ~/Developer/aayush/next-portfolio
z blog # jumps to the most-visited directory matching "blog"
zi portfolio # interactive selection if multiple matches
```
**[ripgrep (rg)](https://github.com/BurntSushi/ripgrep)** replaces `grep` and it's not close. Ripgrep is faster, respects `.gitignore` by default (no more sifting through `node_modules` results), and supports PCRE2 regex. For [building this blog with MDX](/blog/build-a-blog-with-nextjs-and-mdx), I use `rg` constantly to search across content files and component code simultaneously.
```bash title="Terminal"
# search only TypeScript files for a component usage
rg "MDXRemote" --type ts
# find all TODOs — .gitignore respected automatically, no node_modules noise
rg "TODO|FIXME"
# count matches per file for a quick usage audit
rg "useState" --count --sort path
```
**[delta](https://github.com/dandavison/delta)** makes `git diff` output actually readable. Syntax-highlighted diffs with line numbers, side-by-side view mode, and proper word-level change highlighting. Set it as your git pager once and every `diff`, `log`, and `show` command benefits automatically — zero changes to your workflow.
```ini title="~/.gitconfig"
[core]
pager = delta
[delta]
navigate = true
side-by-side = true
line-numbers = true
[interactive]
diffFilter = delta --color-only
```
> Four aliases — `ls`, `cd`, `grep`, `cat` — all pointing to faster tools. Same muscle memory, better output. That's the ideal upgrade path.
## API and database tools
I burned out on Postman's bloat (500MB for an HTTP client, really?) and switched to terminal-native alternatives. These two cover 95% of what I need without Electron.
**[Posting](https://posting.sh/)** is Postman as a TUI. API collections are plain text files I can version-control, diff, and share through Git. It starts in under a second. No account required, no cloud sync, no team-tier upsell. For testing endpoints during development, it's everything I need and nothing I don't.
**[Harlequin](https://harlequin.sh/)** is a lightweight SQL client that works with Postgres, SQLite, and DuckDB. I was using DataGrip but the JetBrains startup time was killing quick database checks — "let me verify this query" shouldn't require waiting 15 seconds for a Java app to boot. Harlequin is instant, keyboard-driven, and has autocomplete for table and column names.
## How it all connects: a real workflow
The individual tools matter less than how they compose. Here's what a typical coding session looks like end to end.
I open Wezterm. Tmux automatically attaches my last session — three windows already arranged: editor, server, and git. I hit `Ctrl+Shift+P` to open my project switcher (FZF scanning `~/Developer`), type "port" to fuzzy-match my portfolio repo, and I'm in the project root.
Neovim opens with Telescope ready. I type `ff`, search for the component I need to change, and LSP has diagnostics loaded before my fingers leave the keyboard. After making changes, I split a Tmux pane, run the dev server, and preview in the browser.
When I'm ready to commit, `lg` aliases to Lazygit — I stage hunks visually, write a conventional commit message with Better Commit, and push. The diff shows up syntax-highlighted via delta. The entire flow from "open terminal" to "pushed commit" never touches a mouse.
> The philosophy is home-row efficiency. Every mouse reach is a context switch, and context switches are where focused work goes to die.
That's not theoretical. I timed my workflow before and after the migration. Common operations — finding files, switching projects, staging commits, checking processes — dropped from an average of 8 seconds to under 2. Across a full workday, that's a non-trivial amount of reclaimed focus time.
## What didn't survive the cut
Not everything I tried made it. The purge is the most important part of this system — adding tools is easy, removing them requires honesty about what's actually useful versus what looks cool in a dotfiles screenshot.
**Neofetch/Fastfetch** — Fun for exactly one screenshot. After that, it's a startup script that adds 200ms to every new terminal for information I never look at. Removed after a week.
**Cava** — Audio visualizer in the terminal. Beautiful, completely useless for development work. I kept it for two months because it looked good on r/unixporn. Vanity tool.
**Hyprshot** — Screenshot utility for Hyprland. Replaced with a three-line shell script using `grim` and `slurp` that does exactly what I need without another dependency.
**Starship prompt** — Feature-rich cross-shell prompt. Looked great, added 150ms to prompt rendering. I switched to a minimal custom prompt in my `.zshrc` that shows git branch and exit code. Nothing else.
**Fig (now Amazon Q)** — Autocomplete overlay for the terminal. Clever idea, terrible execution. It intercepted keystrokes, conflicted with FZF, and the AI suggestions were wrong often enough to be distracting rather than helpful. Uninstalled after three days.
## The terminal as an investment
Two years in, the productivity gains are real but they're not the main reason I stayed. The deeper value is *understanding what your tools are doing*. GUI applications hide complexity behind buttons and dropdowns. Terminal tools expose it.
When your build fails, you see the exact command that ran. When your git history is wrong, you see the exact sequence of operations. That transparency makes you a better debugger, a better systems thinker, and — counterintuitively — faster at fixing problems even in GUI-heavy environments because you understand the underlying primitives.
The honest cost: the first month was slower. Significantly slower. I had to look up keybindings constantly, my Neovim config broke weekly, and I missed VS Code's "it works out of the box" convenience. If you're considering this switch, budget real time for the transition and don't do it the week before a deadline. The payoff comes, but it's not instant.
I'm watching a few tools for potential additions: [Ghostty](https://ghostty.org/) as a Wezterm alternative (Zig-based, extremely fast, but still maturing), [Helix](https://helix-editor.com/) as a post-Vim modal editor (built-in LSP, no plugin management, but the ecosystem is thin), and [Claude Code](https://docs.anthropic.com/en/docs/claude-code) for AI-assisted development directly in the terminal — the only AI tool I've tried that fits a keyboard-driven workflow instead of fighting it.
The filter stays the same: if it doesn't make me measurably faster after two weeks of honest use, it gets cut. That filter is the whole point of this setup. The specific tools will change — the discipline of cutting what doesn't earn its place won't.
---
## Build a Blog with Next.js and MDX from Scratch
> File-based content, zero database, full control. A complete walkthrough of building a statically-generated blog with Next.js, MDX, and gray-matter.
- Author: Aayush Bharti
- Published: Wed Mar 12 2025 00:00:00 GMT+0000 (Coordinated Universal Time)
- Updated: Sat Feb 21 2026 00:00:00 GMT+0000 (Coordinated Universal Time)
- Tags: nextjs, mdx, react, tutorial
- Reading time: 11 min
- URL: https://aayushbharti.in/blog/build-a-blog-with-nextjs-and-mdx
Every blog platform wants to be your landlord. They give you a database you can't export, an editor you can't customize, and a design system that looks identical to the thirty thousand other blogs on the same platform. Then they raise the price.
MDX with Next.js App Router flips that entire dynamic: your content lives as files in git, renders through React components you control, and deploys as static HTML to whatever host you choose. No vendor lock-in, no migration anxiety, no monthly invoice for the privilege of writing markdown. You own the content, the rendering pipeline, and the styling.
This is the setup I use for this blog. I'm going to walk you through building it from scratch — TypeScript, App Router, server components, the works.
## The stack (three packages, that's it)
Before we start scaffolding, here's what we're installing and why each one earns its spot:
- **[next-mdx-remote](https://github.com/hashicorp/next-mdx-remote)** — compiles and renders MDX inside React Server Components without bundling content at build time
- **[gray-matter](https://github.com/jonschlinkert/gray-matter)** — extracts YAML frontmatter from your `.mdx` files into typed JavaScript objects
- **[reading-time](https://github.com/ngryman/reading-time)** — estimates how long a post takes to read, so you can display "5 min read" without guessing
That's the entire content layer. No CMS SDK, no GraphQL client, no ORM. If you're coming from a [terminal-first setup](/blog/terminal-first-dev-setup), this will feel familiar — everything is files and functions.
```bash title="Terminal"
pnpm create next-app@latest mdx-blog --typescript --tailwind --app --src-dir=false
cd mdx-blog
pnpm add next-mdx-remote gray-matter reading-time
```
## Project structure
The App Router convention makes the mapping between URLs and files dead obvious. Content goes in `content/blog/`, utilities go in `lib/`, and the two route files handle listing and rendering.
```
app/
blog/
[slug]/
page.tsx
page.tsx
layout.tsx
page.tsx
content/
blog/
my-first-post.mdx
building-in-public.mdx
lib/
content.ts
```
Each `.mdx` file in `content/blog/` becomes a blog post. The filename is the slug. No routing config, no database entries, no CMS sync — drop a file in and it exists.
Want to delete a post? Delete the file. Want to rename a URL? Rename the file. The filesystem is the single source of truth, and git is your audit trail.
Notice there's no `components/` or `styles/` folder in this tree — we'll add custom components later. Start lean, add complexity when you have a reason to.
## Frontmatter contract
Before writing any loader code, define what every blog post must include. This is a contract between your content and your rendering layer — if a field is missing, TypeScript catches it at build time instead of your readers catching a broken page in production.
```ts title="lib/content.ts"
interface BlogFrontmatter {
title: string;
publishedAt: string;
description: string;
image: string;
author: string;
tags: string[];
}
interface BlogPost {
slug: string;
frontmatter: BlogFrontmatter;
content: string; // [!code highlight]
readingTime: string;
}
```
The `content` field holds the raw MDX string — we don't serialize it ahead of time because `next-mdx-remote/rsc` handles compilation inside the server component. That distinction matters: the RSC version compiles on the server during rendering, not during a separate build step.
> **Why type frontmatter?**
>
> I've shipped posts with missing `description` fields before. The page rendered fine — until social previews showed "undefined" as the meta description across every platform. Type-safe frontmatter prevents that entire class of bug.
## Content layer
All the filesystem logic lives in one file. Two functions, no abstractions, no class hierarchy. The file system is the database and `gray-matter` is the query engine.
```ts title="lib/content.ts"
import fs from "node:fs";
import path from "node:path";
import matter from "gray-matter";
import readingTime from "reading-time";
const POSTS_DIR = path.join(process.cwd(), "content", "blog"); // [!code highlight]
/** Return metadata + raw MDX for every published post, sorted newest-first. */
export function getAllPosts(): BlogPost[] {
const files = fs.readdirSync(POSTS_DIR).filter((f) => f.endsWith(".mdx"));
return files
.map((filename) => {
const slug = filename.replace(/\.mdx$/, "");
const raw = fs.readFileSync(path.join(POSTS_DIR, filename), "utf-8");
const { data, content } = matter(raw);
return {
slug,
frontmatter: data as BlogFrontmatter, // [!code highlight]
content,
readingTime: readingTime(content).text,
};
})
.sort(
(a, b) =>
new Date(b.frontmatter.publishedAt).getTime() -
new Date(a.frontmatter.publishedAt).getTime()
);
}
/** Return a single post by slug, or null if it doesn't exist. */
export function getPostBySlug(slug: string): BlogPost | null {
const filePath = path.join(POSTS_DIR, `${slug}.mdx`);
if (!fs.existsSync(filePath)) return null; // [!code highlight]
const raw = fs.readFileSync(filePath, "utf-8");
const { data, content } = matter(raw);
return {
slug,
frontmatter: data as BlogFrontmatter,
content,
readingTime: readingTime(content).text,
};
}
```
`getPostBySlug` returns `null` instead of throwing — the caller decides whether a missing post is a 404 or an error. We're reading files synchronously because this runs server-side during static generation; there's no event loop to block, and `fs.readFileSync` is actually faster than its async counterpart for small files.
## Blog listing page
The listing page is an async server component. No `"use client"`, no `useEffect`, no loading states. It calls `getAllPosts()` at render time, and because Next.js statically generates App Router pages by default, this runs once at build time and outputs pure HTML.
```tsx title="app/blog/page.tsx"
import Link from "next/link";
import { getAllPosts } from "@/lib/content";
export const metadata = {
title: "Blog",
description: "Articles on web development, tooling, and building in public.",
};
export default function BlogPage() {
const posts = getAllPosts(); // [!code highlight]
return (
Blog
{posts.map((post) => (
{post.frontmatter.title}
{post.frontmatter.description}
{post.readingTime}
))}
);
}
```
No data-fetching function to export, no serialization boundary to worry about, no hydration mismatch to debug. The component calls a function, gets data, renders JSX. This is what the App Router was designed for.
If you've used `getStaticProps` in the Pages Router, this is the equivalent — except there's no props object, no serialization boundary, and no separate data-fetching layer. It's a better model once you stop looking for the hooks you're used to.
## Article page
The dynamic route needs three things: `generateStaticParams` to tell Next.js which slugs exist at build time, `generateMetadata` for SEO, and the page component itself that renders the MDX.
```tsx title="app/blog/[slug]/page.tsx"
import { notFound } from "next/navigation";
import { MDXRemote } from "next-mdx-remote/rsc"; // [!code highlight]
import { getAllPosts, getPostBySlug } from "@/lib/content";
interface PageProps {
params: Promise<{ slug: string }>;
}
export async function generateStaticParams() {
return getAllPosts().map((post) => ({ slug: post.slug }));
}
export async function generateMetadata({ params }: PageProps) {
const { slug } = await params;
const post = getPostBySlug(slug);
if (!post) return {};
return {
title: post.frontmatter.title,
description: post.frontmatter.description,
openGraph: {
title: post.frontmatter.title,
description: post.frontmatter.description,
images: [post.frontmatter.image],
},
};
}
export default async function ArticlePage({ params }: PageProps) {
const { slug } = await params;
const post = getPostBySlug(slug);
if (!post) notFound(); // [!code highlight]
return (
{post.frontmatter.title}
·{post.readingTime}
// [!code highlight]
);
}
```
The import is `next-mdx-remote/rsc` — not the default export. This tripped me up the first time. The default `next-mdx-remote` export is designed for the Pages Router: it serializes content in `getStaticProps` and hydrates it on the client.
The `/rsc` export skips all of that — it compiles MDX on the server as part of the React render tree, which means zero client-side JavaScript for your content. The entire article ships as static HTML.
Also note the `params` type: `Promise<{ slug: string }>`. Next.js 15+ made `params` asynchronous in layouts and pages, so you need to `await` it. If you forget, TypeScript will catch it — but the error message is confusing if you don't know what changed.
> If `getPostBySlug` returns `null`, calling `notFound()` triggers Next.js's built-in 404 page. No try-catch, no error boundaries, no conditional renders.
## Custom components
This is the real payoff of MDX over plain markdown. You can pass React components into the renderer and use them directly in your `.mdx` files. A callout box, a responsive image with blur placeholder, a styled link — anything you can build in React, you can embed in your writing.
### The components map
Create a file that maps component names to their implementations. This is what `MDXRemote` uses to resolve JSX tags in your content.
```tsx title="lib/mdx-components.tsx"
import Image from "next/image";
import type { MDXComponents } from "mdx/types";
import { Callout } from "@/components/callout";
export const components: MDXComponents = {
Callout,
Image: (props: React.ComponentProps) => (
),
a: ({ href, children, ...props }) => ( // [!code highlight]
{children}
),
};
```
### A Callout component
This is the component I use most. Tip boxes, warnings, info blocks — one component with a `type` prop.
```tsx title="components/callout.tsx"
import type { ReactNode } from "react";
interface CalloutProps {
type?: "info" | "warning" | "tip";
title?: string;
children: ReactNode;
}
const styles = {
info: "border-blue-500 bg-blue-50 dark:bg-blue-950/30",
warning: "border-amber-500 bg-amber-50 dark:bg-amber-950/30",
tip: "border-purple-500 bg-purple-50 dark:bg-purple-950/30", // [!code highlight]
};
export function Callout({ type = "info", title, children }: CalloutProps) {
return (
{title &&
{title}
}
{children}
);
}
```
### Wiring it up
Pass the components map to `MDXRemote` in your article page:
```tsx title="app/blog/[slug]/page.tsx"
import { components } from "@/lib/mdx-components";
// inside the page component:
// [!code highlight]
```
Now your `.mdx` files can use these components without any imports:
```mdx title="content/blog/my-first-post.mdx"
## Setting up the project
Make sure you have Node.js 18+ and pnpm installed.
Here's what the dashboard looks like:
```
That's the entire value proposition of MDX in one example. Your content is markdown. Your interactive elements are React. They coexist in the same file, version-controlled in the same repo.
You can add as many components as you want — charts, embedded demos, interactive quizzes — without any changes to your rendering pipeline. Add a component, add a key.
## Styling the prose
You've done the hard part — content loads, MDX compiles, components resolve. But if you preview the page right now, you'll notice the rendered HTML looks terrible. Headings have no margins, paragraphs run together, lists have no bullets. That's because Tailwind's preflight strips all default browser styles. The `@tailwindcss/typography` plugin adds them back with a single class.
```bash title="Terminal"
pnpm add @tailwindcss/typography
```
Add the plugin import to your global CSS file (Tailwind v4 uses CSS-based configuration):
```css title="app/globals.css"
@import "tailwindcss";
@plugin "@tailwindcss/typography"; /* [!code highlight] */
```
Wrap your MDX output in a `prose` container. Add `dark:prose-invert` so it respects dark mode.
```tsx title="app/blog/[slug]/page.tsx"
/* [!code highlight] */
```
That single `prose` class applies typographic defaults to every HTML element inside it — headings get proper sizing and spacing, paragraphs get readable line heights, lists get bullets, code blocks get backgrounds, links get underlines. It transforms raw HTML into something that actually looks like a blog post.
The `max-w-none` override lets the container width be controlled by the parent instead of typography's default `65ch`.
> The difference between a blog that looks amateur and one that looks professional is almost entirely typography. `@tailwindcss/typography` gets you 90% of the way there with zero custom CSS.
---
So here's what you've built: a blog where every post is a `.mdx` file in your repo, parsed by `gray-matter`, compiled by `next-mdx-remote`, rendered as a React Server Component, and deployed as static HTML. No database. No CMS. No vendor to migrate away from when they inevitably change their pricing or shut down their API.
Content in git means version history, branch-based drafts, and PR reviews for your writing. Rendering in React means you can embed any component you can build. Static HTML output means it loads fast everywhere and costs almost nothing to host.
From here, the natural next steps are syntax highlighting (look at [rehype-shiki](https://github.com/shikijs/shiki) — it's what I use), an [RSS feed](/blog/rss.xml) for subscribers, and maybe full-text search if your post count warrants it.
If you're still getting your dev environment sorted, [my terminal setup guide](/blog/terminal-first-dev-setup) covers the tooling side. And if you're earlier in the journey — still figuring out whether to even learn to code — I wrote about [what I wish I'd known](/blog/what-i-wish-i-knew-before-learning-to-code) before starting.
But the foundation is solid. Every piece of this system is a plain function or a React component — no framework magic, no generated code, no build step you don't understand. When something breaks (and it will), you'll know exactly where to look. That's the whole point.
You own your content. Ship it.
## Frequently asked questions
### Do I need a database to build a blog with Next.js and MDX?
No. Each post is a .mdx file in your repo, parsed at build time with gray-matter — the filesystem is the database. No Postgres, no CMS, and every post deploys as static HTML.
### What's the difference between Markdown and MDX?
MDX is Markdown that can import and render React components inline. You keep Markdown's simple prose syntax but can drop in interactive components like callouts, steps, or charts where plain Markdown falls short.
### How do I add frontmatter metadata to MDX posts?
Put a YAML block at the top of the file between fence markers (title, date, tags), then parse it with gray-matter. Validate it with a Zod schema so a malformed post fails the build instead of shipping broken.
### Is a Next.js MDX blog good for SEO?
Yes. Posts are statically generated as fast, crawlable HTML, and you can emit per-post metadata, canonical URLs, and BlogPosting JSON-LD from the same frontmatter — structured content for search engines and AI assistants.
---
## What I'd Tell Myself Before Learning to Code
> The myths, mistakes, and mindset shifts that separate people who learn to code from people who quit. Hard-won lessons from my first two years.
- Author: Aayush Bharti
- Published: Thu Dec 05 2024 00:00:00 GMT+0000 (Coordinated Universal Time)
- Updated: Mon Dec 16 2024 00:00:00 GMT+0000 (Coordinated Universal Time)
- Tags: career, learning, developer-mindset
- Reading time: 10 min
- URL: https://aayushbharti.in/blog/what-i-wish-i-knew-before-learning-to-code
I spent a Saturday afternoon in 2022 staring at a function I had written — forty lines of nested `if` statements that checked whether a user's input was a valid email. It worked. It passed the three test cases I had invented. I was proud of it until a friend looked at it and typed a single regex on one line that did the same thing.
That moment captured everything wrong with how I was learning: I was writing code, but I wasn't learning to think in code. The gap between those two activities is where most beginners stall out, and nobody talks about it honestly. Nobody prepares you for the middle part — the six to twelve months where you can make things run but can't explain why they work.
Here's what would have saved me months of thrashing.
## The first month will lie to you
There is a specific kind of high you get when your first program prints "Hello, World" or when your first webpage renders a styled heading. That feeling is real, and it is misleading. The early wins come fast because the problems are constrained: follow these steps, get this output. You're pattern-matching, not problem-solving.
I remember the crash vividly. Three weeks into learning JavaScript, I could follow any tutorial and reproduce the result. Then I closed the tutorial, opened a blank file, and tried to build a simple calculator from scratch. Nothing. I couldn't figure out how to structure the logic without someone holding my hand through each step. The syntax was in my head, but the *thinking* wasn't.
That gap — between recognizing code and producing code — is the first real wall. Experienced developers get stuck too, but they've built mental models for diagnosing problems. That intuition comes from hundreds of hours of writing bad code and fixing it. There is no shortcut through it.
The danger of the first month is that it teaches you a pace of learning that won't hold. You learn `console.log` in five minutes. You do not learn asynchronous programming in five minutes. If you expect the same velocity throughout, you'll interpret the slowdown as personal failure rather than the natural shape of the curve.
## Depth beats FOMO (and framework-hopping will wreck you)
Tech Twitter (or whatever we're calling it now) is engineered to make you feel behind. A new framework drops every week. Some influencer declares that the tool you spent three months learning is dead. Resist the gravitational pull of novelty when you're still building fundamentals.
I fell into this trap hard. During my first year, I touched React, Vue, Svelte, and started a brief fling with Angular before retreating in confusion. The result? I was mediocre at four frameworks instead of competent at one. Every switch reset my mental clock. I'd spend two weeks learning the paradigm, start feeling productive, see a shiny new thing, and jump ship.
The accumulated knowledge from any single framework never compounded because I never stayed long enough. When I finally committed to React and stuck with it for six months straight — building projects, reading source code, understanding the component lifecycle at a level deeper than "it re-renders when state changes" — everything accelerated. Depth in one ecosystem teaches you transferable concepts. Breadth across five ecosystems teaches you setup commands.
> Don't worry about knowing everything. Know one thing well, and the rest becomes learnable.
Tutorial hell is the cousin of framework-hopping. Both feel productive. Both are avoidance strategies. The instructor is doing the hard cognitive work — deciding what to build, how to structure it, which problems to solve first. You're typing along.
The fix is uncomfortable: build something before you're ready. Pick a project you care about and fumble through it. The fumbling is the learning. That's how I ended up [building this blog from scratch with MDX](/blog/build-a-blog-with-nextjs-and-mdx) — I learned more from that one project than from the previous dozen tutorials combined.
## Motivation is a spark, systems are the engine
I've never met a self-taught developer who was consistently motivated for two years straight. Motivation fluctuates. You'll have weeks where you code for four hours after work and weeks where opening VS Code feels like pulling teeth. The people who make it through aren't more motivated — they have better systems.
Here's what worked for me when the initial excitement burned off:
**Set targets with a finish line**
"Learn React" is vapor. "Build a weather app with React that fetches data
from an API and deploy it to Vercel by Friday" is a target. Small completions
build momentum. You can't feel progress toward a vague goal.
**Protect a daily minimum**
Thirty minutes of focused coding daily beats an eight-hour weekend marathon
every time. The daily habit keeps context loaded in your brain. When you skip
three days, you spend the first hour of your next session remembering where
you left off. Consistency compounds; intensity evaporates.
**Find your cohort**
Accountability matters when motivation drops. A Discord server, a local
meetup, a friend learning at the same pace — any of these work. The grind is
less isolating when someone else understands why you've been debugging a CSS
layout for two hours. (Two hours on CSS is not a beginner problem, by the
way. That's a universal experience.)
Bootcamps accelerate by providing structure and deadlines, but they don't compress the hours required. You cannot shortcut pattern recognition. Be suspicious of anyone promising a six-figure salary after eight weeks of study — the realistic timeline from zero to employable is 12 to 24 months of consistent work.
## You don't need math (probably)
This myth stops more people from starting than any other. The belief that programming requires advanced mathematics is wrong for the vast majority of the industry.
Some domains demand it — machine learning, computer graphics, cryptography. Most web development, API design, and automation rely on logic and problem decomposition, not linear algebra. I built full-stack applications for a year before I needed anything beyond arithmetic and boolean logic. Math can be learned later when your work demands it — and it sticks faster with a concrete application.
## Code reviews will teach you faster than any course
The single biggest accelerator in my learning wasn't a course, a book, or a YouTube playlist. It was the first time someone tore apart my pull request.
I had submitted what I thought was clean code — a React component for a side project I was building with a friend. He left fourteen comments. Fourteen. He pointed out that I was mutating state directly, that my useEffect had a missing dependency (and explained why that mattered), that I had hardcoded values that should be constants, and that my variable names read like someone naming pets rather than describing data.
I was embarrassed for about an hour. Then I fixed everything, re-read the comments, and realized I had learned more from that single review than from the previous month of solo study.
Code review exposes blind spots you don't know you have. When you're learning alone, you develop habits — some good, some terrible — and without external feedback, the terrible ones calcify. Getting reviewed forces you to articulate *why* you made a choice. And reviewing other people's code, even when you're new, trains your ability to read unfamiliar codebases.
Start before you feel ready. Small open-source PRs, questions instead of assertions — "Why did you choose X over Y?" teaches you more than silently reading.
## The "no experience" loop is solvable
"We need someone with experience." "How do I get experience without a job?" This loop sounds inescapable, and it isn't.
Companies hire for demonstrated ability, not employment history. Build projects that solve real problems — not todo apps, but tools you'd actually use. Contribute to open source; even documentation fixes count because they show you can navigate a real codebase and communicate with maintainers.
When I built and documented my [terminal-first dev setup](/blog/terminal-first-dev-setup), writing about my tooling choices taught me more than months of passive use. A portfolio with three well-documented projects beats a resume with ten buzzwords.
## AI is a power tool, not a replacement for understanding
This section didn't exist two years ago. Now it's mandatory.
GitHub Copilot and ChatGPT have fundamentally changed what it feels like to learn to code. You can describe a problem in English and get working code back in seconds. This is extraordinary. It is also a trap if you don't use it carefully.
I've caught myself copy-pasting AI-generated code without understanding what it does. It runs, the tests pass, you move on — then something breaks and you're staring at code you can't debug because you never understood it. A new flavor of tutorial hell, except infinite and personalized.
> Copy-pasting AI output without understanding it is tutorial hell with better autocomplete.
Here's the line I try to hold: use AI to get *unstuck*, not to avoid *thinking*. Copilot saving me a trip to the docs for a TypeScript utility type? Useful. Asking ChatGPT to "build me an authentication system" and dropping the result into my project? That's outsourcing the learning.
The goal isn't shipping code — it's becoming someone who can ship code without the crutch. AI raises the floor, but it doesn't raise the ceiling unless you understand the output well enough to modify and debug it. Before you commit AI-generated code: can you explain every line? Can you modify it without re-prompting? If not, you haven't learned — you've delegated.
## The Dunning-Kruger curve is real, and the valley is where growth lives
This graph captures the learning arc better than any advice thread I've read.
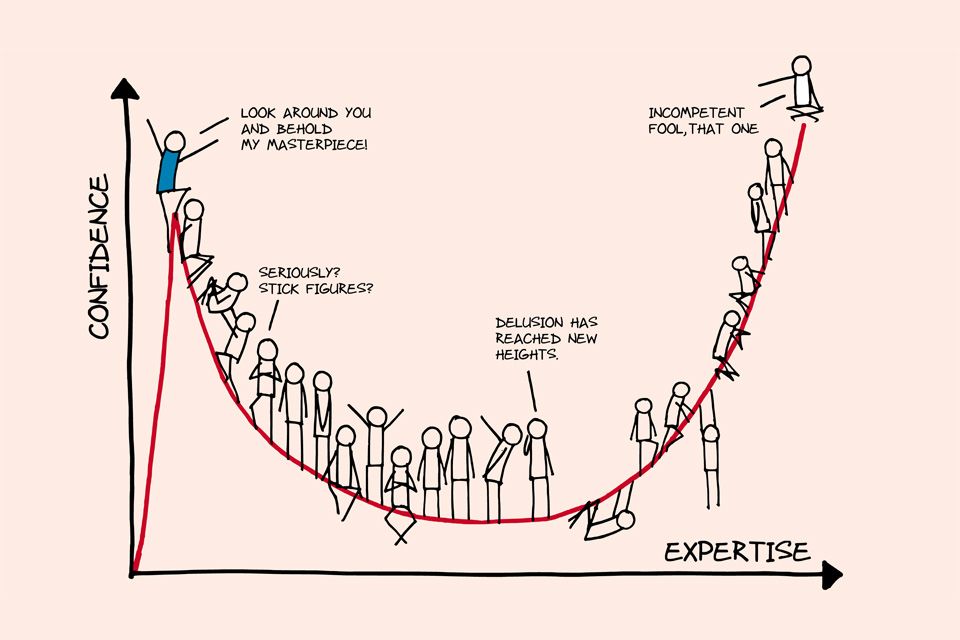
You start overconfident — "I built a website in a weekend, how hard can this be?" Then you hit real problems: asynchronous code that behaves in ways you can't predict, state management that spirals, deployment pipelines that break silently. Confidence craters. You enter the valley where you know enough to see how much you don't know, and it feels worse than the beginning because at least the beginning had momentum.
The valley is where most people quit. It's also where the actual learning happens, because you're finally encountering problems complex enough to force deep understanding. The inflection point comes when debugging stops feeling like magic and starts feeling like detective work — when you read an error message and immediately know which file to open, which assumption to question, which log to check.
You don't cross that threshold by watching someone else debug. You cross it by debugging your own broken code at 11 PM, tracing a null reference through four function calls, and finally understanding why your data was undefined. That specific frustration is the learning. Every resolved bug deposits a small amount of pattern recognition that compounds over years.
The middle part — where you can write code that runs but can't explain why — doesn't last forever. It feels permanent while you're in it. The developers you admire went through it. They didn't have a secret; they had time and stubbornness.
If you're in the valley right now, the only difference between you and the people who made it through is that they didn't stop. They built systems that kept them writing code on the days they didn't want to. The inflection point is coming — you won't recognize it when it arrives, only months later when the problems that used to paralyze you feel routine.
---
# Projects
## Keythm
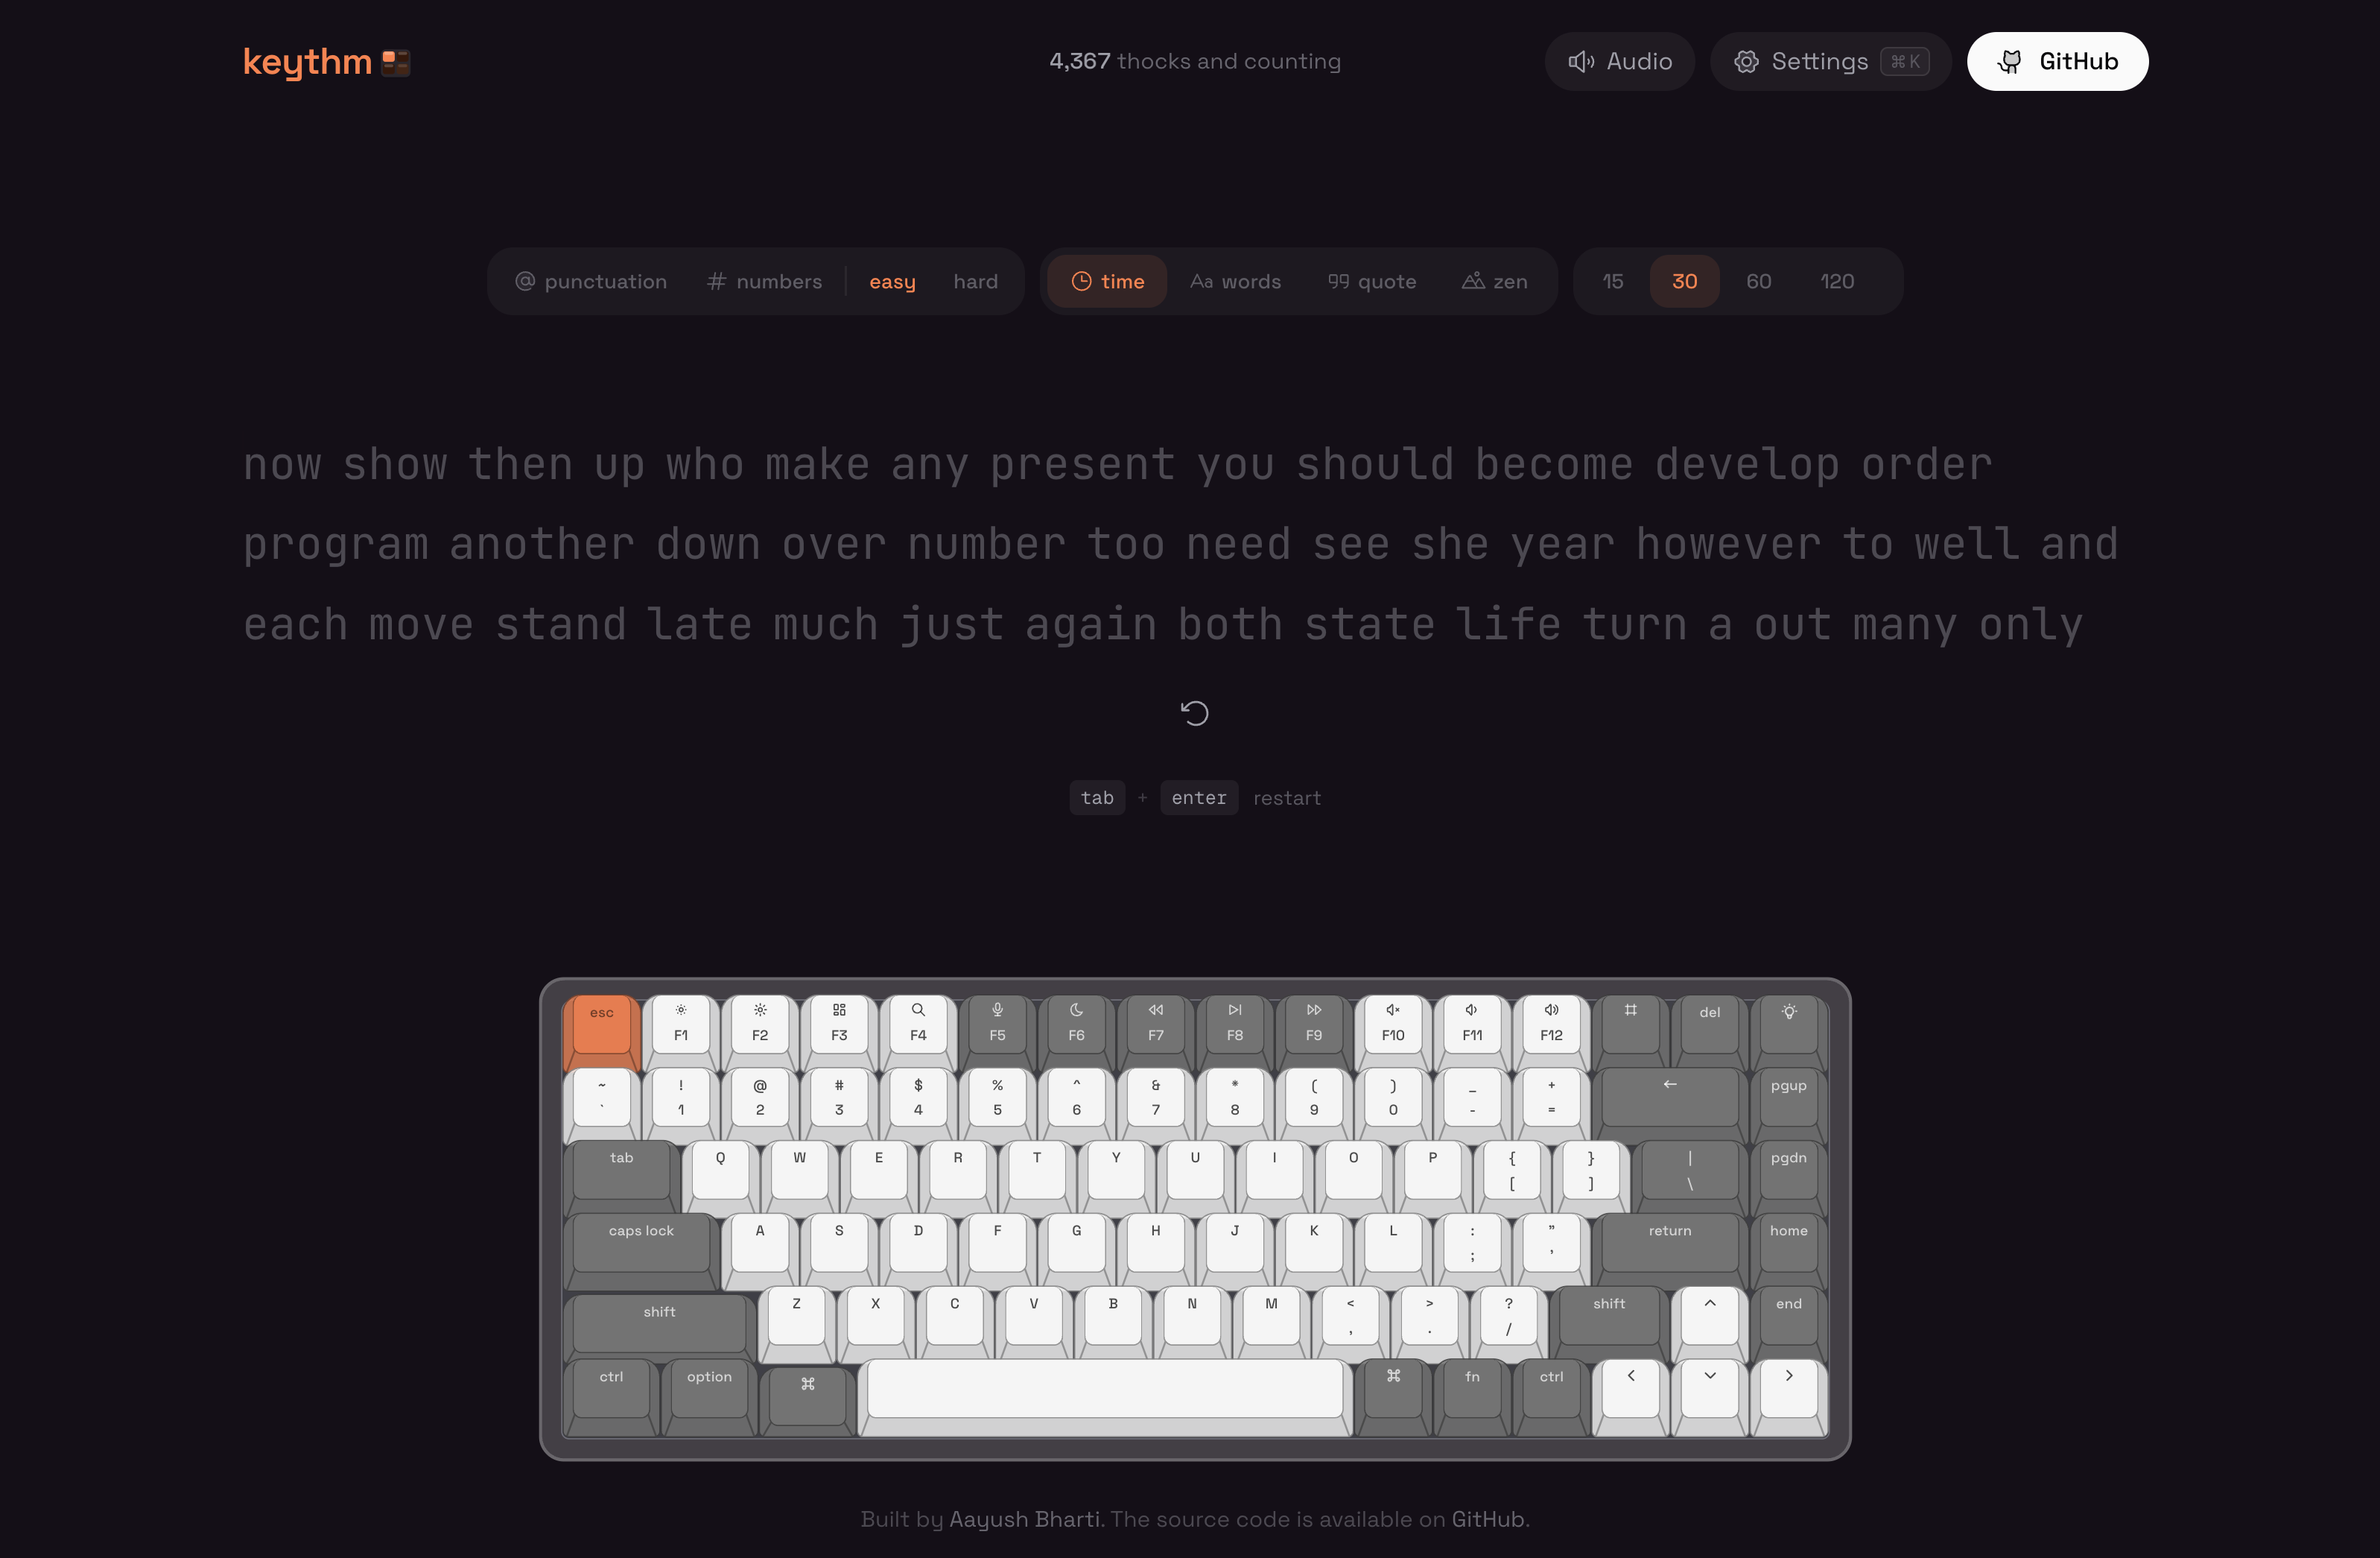
> A typing test where every key has its own sound. Per-key mechanical audio via Web Audio API, four test modes, statistical anti-cheat, and a fully offline PWA — built to make typing feel physical.
- Tech: nextjs, react, typescript, tailwindcss, drizzle, motion, shadcn-ui, web-audio-api, serwist, zod, recharts
- Published: 2026-05-04
- Live: https://keythm.aayushbharti.in
- Repo: https://github.com/aayushbharti/keythm
- URL: https://aayushbharti.in/projects/keythm
## Why I Built This
Every typing test I used got the basics right and stopped there. Monkeytype is feature-complete but heavy. Most alternatives show you a WPM number and call it a day — no sound, no personality, no breakdown of what actually happened during the test.
I wanted typing to feel physical in the browser. I use mechanical keyboards daily, and the disconnect between pressing a real switch and hearing silence in a web app always bothered me. Not a generic click — actual per-key audio, so pressing `Q` sounds different from pressing `Enter`. That one constraint shaped every technical decision that followed.
---
---
## Sound System
Sound is the whole reason Keythm exists, so it had to be indistinguishable from real keystrokes — and fast enough that you'd never notice it wasn't.
The entire library lives in a **single 1.9MB OGG sprite**: ~80 key samples packed into one file, each mapped to a `[startMs, durationMs]` tuple for both the "down" and "up" phase. On first load, the sprite gets fetched and decoded into an AudioBuffer at module import time — before any component mounts. When you press a key, `BufferSource.start(0, offset, duration)` slices the right sample on demand. One HTTP request, one decode, and latency that stays under a single frame.
The part that took the most debugging was browser restrictions. Modern browsers suspend new AudioContexts until the user interacts with the page (thanks, autoplay policies). Keythm listens for the first `keydown` or `pointerdown` on the document and resumes the context immediately — so the audio pipeline is warm by the time you actually start typing. There's also a `modifiersDownRef` to track held modifier keys, because macOS has a lovely habit of swallowing keyup events after Cmd chords.
And then there's "faah mode" — an Easter egg that plays a dramatic sound effect on wrong keys. It uses a plain HTML Audio element because, honestly, it doesn't need the precision of the sprite system.
---
## Typing Engine & Results
The core hook — `useTypingTest` — manages the full lifecycle across four modes: **timed** (15–120s), **word count** (10–100), **curated quotes** (filtered by length), and **zen** (unlimited, Shift+Enter to end).
Every second, the engine snapshots WPM, raw WPM, and error count. Those snapshots drive three things: the live stats overlay while you type, the WPM-over-time chart on the results screen, and the consistency score (100 minus the coefficient of variation of per-second WPMs — high consistency means steady rhythm, low means erratic bursts).
Results give you six metrics: WPM, raw WPM, accuracy, consistency, elapsed time, and a character-level breakdown (correct, incorrect, extra, missed, corrected). The Recharts graph shows exactly where you sped up, lost focus, or hit a wall. Score 100+ WPM and confetti fires — tuned to feel celebratory without being annoying.
**Anti-cheat** was more interesting than I expected. Simple threshold checks — WPM above 300, raw above 350, more than 30 chars/sec — catch the obvious bots. But the interesting cheats are scripts that type at 120 WPM with inhuman consistency. Catching those required statistical analysis: flat WPM history (every second within 1 WPM of every other), perfect consistency at high speed, impossible single-second bursts above 600 WPM, and AFK gaps mid-test. All 13 checks only activate above 80 WPM — slow-but-steady typists shouldn't get flagged for being consistent.
---
## Key Decisions
### Single sprite over 80+ audio files
The alternative was individual files per key — 80+ HTTP requests (or a bundling step that would need its own maintenance), 80+ decode calls, and cache invalidation headaches. A single sprite with offset tuples keeps the entire sound system in one fetch and a lookup table. The tradeoff is manual offset mapping, but that's a one-time cost paid once during development.
### localStorage-first, server-optional
All settings, personal bests, and preferences persist to localStorage with a `tc-` prefix. No auth, no round-trips. Combined with Serwist's precaching, the app works fully offline after the first visit. Drizzle + LibSQL is wired up for future aggregate features (leaderboards, distribution curves), but nothing in the core experience depends on it. If the server is unreachable, nothing breaks — you just don't get global stats.
### Blocking script for theme hydration
A tiny inline script in `` reads the accent color from localStorage before the first paint. Every React app with persisted themes has the same flash-of-wrong-color problem; this solves it by running before hydration. The page loads with correct colors from the first frame.
### IntersectionObserver gating on the keyboard
The virtual keyboard renders a full QWERTY layout with spring-animated keys (stiffness: 700, damping: 38). That's a lot of event listeners and DOM work. An IntersectionObserver at 10% threshold detaches physical key listeners when the keyboard scrolls out of view. No wasted work, no frame drops on the typing input above it.
## What I Learned
**Sound is the hardest kind of UX polish.** Visual feedback is forgiving — a 50ms delay on a hover state is invisible. Audio feedback at 50ms delay feels broken. The entire sound pipeline (eager fetch, pre-decode, sprite slicing) exists to keep latency under one frame. The gap between "has sound" and "sounds right" is an order of magnitude of engineering effort.
**Anti-cheat is adversarial thinking, not validation.** Threshold checks are table stakes. The interesting problem is detecting a script that types at 120 WPM with near-perfect consistency — plausible speed, inhuman steadiness. Solving that required statistical analysis of the WPM distribution, not bounds checking on the final number. Calibrating thresholds to avoid false positives on legitimate fast typists was the hardest part.
**Offline-first is a forcing function.** Once you commit to "works without a connection," you stop reaching for server state by default. Settings become localStorage. Preferences become client-side. The server becomes optional infrastructure for features that genuinely need it. That constraint produced a simpler, faster app than "add offline support later" ever would have.
---
---
## Nextdemy
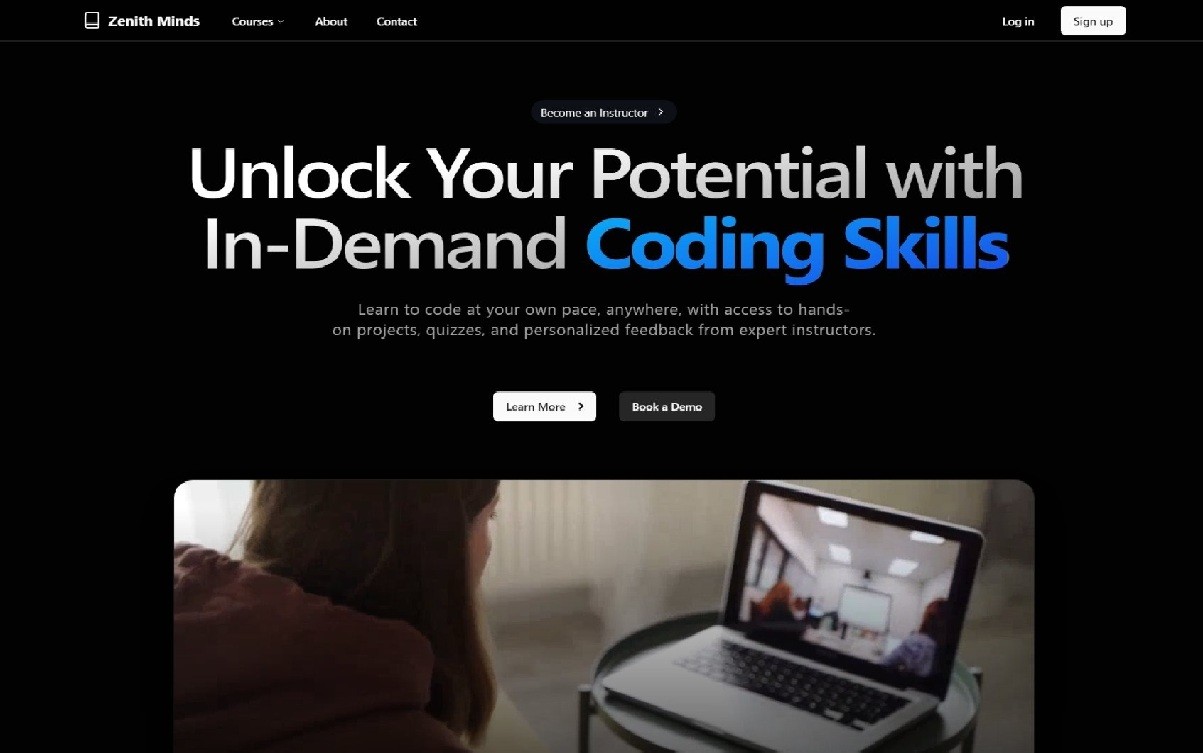
> Full-stack EdTech platform with course marketplace, Razorpay payments, video streaming, and role-based dashboards for students and instructors.
- Tech: nextjs, typescript, tailwindcss, tanstack-query, zustand, shadcn-ui, motion, express, bun, mongodb, zod, razorpay, turborepo, docker
- Published: 2024-10-01
- Live: https://academy.aayushbharti.in
- Repo: https://github.com/AayushBharti/Zenith-Academy
- URL: https://aayushbharti.in/projects/nextdemy
## Why I Built This
Most EdTech codebases I'd seen were monoliths held together by duct tape — tangled auth, payment flows with no observability, and frontend/backend types that drifted silently until something broke in production. I wanted to build one properly. Not to prove I could use the tech, but to prove I could make the hard calls: where to draw module boundaries, how to handle a payment webhook that fires twice, what breaks when your server cold-starts mid-token-refresh.
---
---
## How It Works
Two audiences, two very different workflows. **Students** browse a course catalog, pay via Razorpay, stream video content, track progress per-subsection, and leave ratings. **Instructors** build courses through a structured editor — sections contain subsections, each with a video URL — upload media through Cloudinary, and monitor enrollments and revenue from a dedicated dashboard.
The architecture is a **Turborepo monorepo** with three workspaces:
```
apps/
web/
Next.js 16 · React 19 · App Router
api/
Express · Bun · Domain modules
packages/
shared-types/
Zod schemas consumed by both apps
ui/
shadcn/ui component library
typescript-config/
Shared TSConfig presets
```
That `shared-types` package is the load-bearing wall. A field rename breaks both codebases at compile time, not in production at 2 AM.
State ownership is explicit. **React Query** handles everything from the server — courses, profiles, payment history. **Zustand** handles everything client-only — auth tokens in memory, cart persisted across reloads. No overlap. An Axios interceptor bridges them: on a 401, it queues pending requests, refreshes via httpOnly cookie, replays the queue. The user never sees the handshake.
---
### Rolling my own auth
Bcrypt for hashing. Short-lived JWTs in memory. Refresh tokens in httpOnly cookies. OTP email verification. Role-based middleware — Student, Instructor, Admin. I wrote every layer instead of reaching for a library, and it paid off the first time something broke. (Cold starts on Render made the refresh endpoint take 3 seconds to wake. The Axios interceptor now retries with backoff and queues concurrent requests. That fix took an hour because I understood the full chain.)
### Razorpay payments
HMAC signature verification, idempotent enrollment keyed on `razorpay_order_id`, `CourseProgress` creation, and confirmation emails via Resend. The Payment model tracks explicit status transitions — pending, success, failed — with the full Razorpay reference chain. I didn't build that tracing for fun. I built it after v1 had zero observability and debugging "where did my money go" was guesswork.
### Shared Zod schemas
```ts title="packages/shared-types/src/course.ts"
export const createCourseInput = z.object({
courseName: z.string().min(3),
courseDescription: z.string().min(10),
price: z.number().min(0),
tag: z.array(z.string()),
category: z.string(),
instructions: z.array(z.string()),
});
export type CreateCourseInput = z.infer;
```
Both apps import `CreateCourseInput` directly. Before this, I maintained parallel interfaces that drifted. I'd find out from a 500 in production. Now a breaking change is a compile error. Simplest decision, highest return.
### Bun everywhere
Both apps run on Bun — fast cold starts, native TypeScript, no dev build step. `bun install` at the root, Turbo orchestrates parallel builds, each app Dockerized with multi-stage builds (~30 lines per Dockerfile). One runtime, one package manager. The less context switching between tools, the faster I ship.
---
The Express API is organized by domain, not technical layer. Each module — auth, course, payment, profile, upload — co-locates its routes, controllers, services, and Mongoose models. Controllers validate input against shared Zod schemas, delegate to services, return through a standardized `ApiResponse` utility. No controller touches `res.status().json()` directly — that inconsistency bit me in a previous project. Once two controllers format errors differently, every frontend dev writes defensive parsing forever.
Middleware runs in a deliberate order: rate limiting → body parsing → CORS → Helmet → cookies → Morgan → mongo-sanitize → routes → global error handler. Auth middleware lives at the route level, not globally. (I learned why after accidentally gating my health check and watching the load balancer panic.)
Error handling is discriminated:
```ts title="shared/utils/api-error.ts"
// Expected failures — typed, clean responses
throw ApiError.badRequest("Course name is required");
throw ApiError.unauthorized("Token expired");
throw ApiError.notFound("Course not found");
// Unexpected failures — logged via Pino, generic message to client
// Internal details never leak.
```
I added that "never leak" rule after a Mongoose validation error exposed the entire document schema to a user.
---
## Challenges
> **Double enrollment on webhook retries**
>
> v1 trusted that Razorpay's webhook would fire exactly once. It doesn't. A network timeout triggered a retry, students got enrolled twice — duplicate `CourseProgress` documents, duplicate emails. Fix: idempotent enrollment keyed on `razorpay_order_id` with a unique index. Simple in retrospect, invisible until it happened.
> **Silent logout on cold starts**
>
> Free-tier hosting sleeps the server after inactivity. First request back takes 2–3 seconds. If that request is a token refresh, the frontend sees a 401, clears the session, and the user gets logged out silently. Fix: Axios interceptor retries with a 2-second delay and queues every concurrent request during the refresh window.
> **Leaked Mongoose schema to client**
>
> An unhandled Mongoose validation error surfaced the entire document schema in a 500 response. Fix: discriminated error handling — expected failures return typed `ApiError` envelopes, unexpected errors log full traces via Pino but return generic messages. Internal details never reach the client.
---
## What I Learned
**Shared types are the highest-leverage thing you can add to a full-stack repo.** The Turborepo setup took an afternoon. It's caught type drift every week since. Every full-stack project I build from now on starts with a shared schema package.
**Payment integrations are straightforward until they aren't.** The happy path is a day. Edge cases — signature failures, duplicate deliveries, partial rollbacks, "user closed browser mid-checkout" — are the rest of the week. Status tracking and idempotency aren't optional.
**Architecture opinions compound.** Domain-organized modules, discriminated error types, explicit state ownership, standardized API responses — individually, each is a small decision. Together, they're the reason I can add a feature without re-reading the entire codebase.
---
---
## VentureDen
> An AI-powered startup pitch platform built on Next.js 16 and Sanity CMS, where founders pitch ideas, get instant Gemini-powered feedback, and connect with investors.
- Tech: nextjs, react, typescript, sanity, groq, tailwindcss, motion, react_query, zod, turborepo, pnpm, markdown
- Published: 2025-01-01
- Live: https://venture-den.aayushbharti.in
- Repo: https://github.com/AayushBharti/VentureDen
- URL: https://aayushbharti.in/projects/venture-den
## Why I Built This
I wanted a project at the bleeding edge of the Next.js ecosystem — Next.js 16, React 19, the React Compiler, Turbopack — paired with a real product problem rather than a toy demo. Reading release notes isn't enough; I needed an app with authentication, user-generated content, and a CMS to understand how these pieces behave together in production.
A startup pitch platform was the right shape: founders submit pitches, the community upvotes and comments, and — the part I was most excited about — **every pitch gets scored by AI**. That gave me a reason to wire up a structured LLM pipeline alongside a content-managed marketing site, all inside a single monorepo.
---
---
## How It Works
Founders sign in with **GitHub OAuth** (NextAuth v5) and submit a pitch through a multi-step form with a Tiptap/Novel rich-text editor. On submission, the pitch is sent to **Google Gemini**, which returns a structured analysis — scores for **clarity, market positioning, and uniqueness**, a weighted overall score, and a handful of actionable suggestions. The response is validated with Zod before it ever touches the UI, so a malformed model output can't break the page.
Content lives in **Sanity CMS**. The entire marketing surface — homepage hero, logo ticker, top pitches, integrations, FAQ — is a typed page builder editable by non-technical users, with click-to-edit visual editing and live preview wired through GROQ queries and Sanity's live content API.
The browse experience layers category filters, sorting by recent/upvotes/views, and instant client-side fuzzy search with Fuse.js. Upvotes, comments, and view counts are persisted back to Sanity, and each founder gets a public profile generated automatically on first sign-in.
---
---
## Key Decisions
### A pnpm + Turborepo monorepo
The Next.js frontend and the Sanity Studio live in one repo with shared packages for env validation, the Sanity client and generated types, the UI kit, and logging. Turborepo's task graph caches lint/typecheck/build across both apps, and generated Sanity types flow straight into the frontend — so a schema change is type-checked end to end.
### Structured AI output over free-form text
The temptation with an LLM feature is to dump prose on the screen. Instead I forced Gemini's response into a strict schema and validated it with Zod, then rendered each dimension as its own scored panel. Treating the model as a typed data source — not a chat box — made the feature reliable enough to ship and trivial to redesign.
### Sanity CMS over a custom database
For a content-heavy app with structured, editor-managed data, Sanity beat rolling my own Prisma + Postgres layer. GROQ is expressive, the Studio gives a visual page builder, and live queries mean the feed and homepage update the moment content is published — no redeploy.
---
---
## What I Learned
**Treat LLMs as typed APIs, not chatbots.** The moment I constrained Gemini to a schema and validated it, the AI feature went from a fragile party trick to a dependable part of the product. Validation at the boundary is what makes generative features production-safe.
**Monorepos pay off when types cross boundaries.** Having the Studio schema regenerate the exact TypeScript types the frontend consumes caught a whole class of bugs at compile time. The upfront wiring of Turborepo and shared packages saved time on every subsequent feature.
**The newest features need patience.** Next.js 16, React 19, and the React Compiler were fast-moving targets with sparse docs. Reading source and GitHub discussions for edge cases no tutorial covered yet was just part of the work — and the payoff was a genuinely fast, modern app.
---
---
## Finote
> A personal finance manager with multi-wallet support, real-time spending analytics, and receipt capture.
- Tech: react-native, expo, typescript, firebase, zod, zustand, cloudinary, reanimated, gifted-charts
- Published: 2025-10-01
- Live: https://github.com/AayushBharti/finote-app/releases/
- Repo: https://github.com/aayushbharti/finote-app
- URL: https://aayushbharti.in/projects/finote
## Why I Built This
Every finance app I tried either felt like enterprise software or lacked the features I actually needed. I wanted something in between — a personal tool that could handle multiple wallets, show me clear spending trends, and let me snap receipts on the go. So I built it myself.
Finote was also my deep dive into React Native. I wanted to move beyond web and understand mobile-specific constraints: gesture handling, 60fps animations on lower-end devices, and offline-first data patterns.
---
---
## How It Works
The app revolves around **wallets** — you create buckets like Salary, Freelance, or Cash, and log transactions against them. Each transaction can have a category, amount, notes, and an optional receipt photo.
The home screen shows a real-time snapshot: total balance across wallets, recent transactions, and an interactive bar chart (weekly or yearly view) powered by **react-native-gifted-charts**. You can drill into any wallet to see its individual history and trends.
All data syncs through **Firebase** — Firestore for structured data, Firebase Auth for login. Receipt images upload to **Cloudinary** for optimization and CDN delivery, keeping the app lightweight even with heavy media usage.
---

---
## Key Decisions
### Zustand over Context for state management
React Context re-renders the entire tree on any change. For a finance app where the transaction list, wallet balances, and chart data all update independently, Zustand's selector-based subscriptions made a significant difference in keeping the UI snappy.
### Optimistic UI for transaction creation
When a user logs a transaction, the local state updates immediately. Firestore syncs in the background. If the sync fails, the state rolls back with a toast notification. This pattern eliminates the perceived latency of network requests and keeps the app feeling instant.
### Reanimated for custom animations
The default Animated API couldn't hit 60fps for the custom tab bar and chart transitions I wanted. Reanimated runs animations on the native thread, which made complex gestures and spring-based transitions smooth even on mid-range devices.
### Blob uploads instead of base64
My first attempt at receipt uploads sent base64-encoded strings directly. This bloated payloads and blocked the main thread during encoding. Switching to Blob-based FormData uploads cut transfer sizes and made uploads non-blocking, keeping the app responsive during file transfers.
---
---
## What I Learned
**Mobile data density requires careful design.** Rendering financial data on small screens is a constant tradeoff between granularity and readability. I customized Gifted Charts extensively to ensure touch targets stayed accessible and animations held at 60fps even with yearly datasets.
**Offline-first thinking changes your architecture.** Even though Finote isn't fully offline-capable, designing with optimistic updates and background sync forced me to think about state consistency in ways that web development rarely does.
**React Native has its own performance culture.** Bridge calls, JS thread blocking, and re-render cascades are problems you don't encounter on the web. Profiling with Flipper and understanding the Reanimated worklet model were essential skills I picked up.
---
---
## StarForge
> A sleek and modern AI SaaS landing page built for performance and visual impact. Designed with a focus on engaging UI/UX and smooth parallax interactions.
- Tech: nextjs, react, typescript, tailwindcss, parallax, vercel
- Published: 2024-01-01
- Live: https://ai-saas-landing-starter.vercel.app
- Repo: https://github.com/AayushBharti/ai-saas-landing-starter
- URL: https://aayushbharti.in/projects/star-forge
## Why I Built This
I noticed that most AI SaaS landing page templates were either over-designed to the point of being unusable, or so minimal they felt generic. I wanted to build something in the middle — visually striking enough to capture attention, but structurally clean enough that a founder could fork it and ship within a day.
It was also an exercise in pure frontend craft. No API, no database, no auth — just layout, typography, motion, and performance.
---

---
## How It Works
StarForge is a single-page marketing template with multiple sections: hero with animated gradient, feature grid, pricing cards, testimonials, and a CTA footer. The entire page is statically generated with Next.js and deployed on Vercel.
The visual depth comes from **react-just-parallax** — scroll-driven effects that shift background elements at different speeds, creating a layered 3D feel without any actual 3D rendering. Combined with Motion.dev transitions for section reveals, the page feels alive without being heavy.
Styling is entirely Tailwind CSS with a custom design token layer. Colors, spacing, and typography are defined as variables, so rebranding the template to a different product takes minutes instead of hours.
---
---
## Key Decisions
### Parallax over 3D
I considered using Three.js or Spline for the hero section, but the performance cost wasn't worth it for a landing page. Parallax scroll effects achieve 90% of the visual impact at a fraction of the bundle size and work reliably across all devices.
### Static generation only
There's no dynamic content on a marketing landing page. Full static generation means the page loads from CDN in every region, scores perfectly on Core Web Vitals, and costs nothing to host.
### Design tokens for rebranding
Rather than hardcoding colors and spacing, I extracted everything into Tailwind config variables. This makes the template genuinely reusable — swap the color palette and logo, and you have a distinct-looking page.
## What I Learned
**Scroll-based animations need performance budgets.** Parallax effects are easy to implement but easy to over-do. Every additional layer reduces frame rates on mobile. I learned to profile on real devices and cut effects that didn't justify their performance cost.
**Typography carries landing pages.** The difference between a professional and amateur landing page is often just font choice, size hierarchy, and line height. I spent more time on type than on any other visual element.
**Constraints produce better work.** No backend, no auth, no database — just HTML, CSS, and motion. The constraint forced me to focus entirely on craft, and the result is tighter because of it.
---
---
## Snippix
> A powerful tool for sharing beautiful, customizable code snippets across social media. Supports multiple languages, themes, and export formats — built for developers who care about presentation.
- Tech: nextjs, react, zustand, typescript, shadcn-ui, tailwindcss, highlightjs, react-hotkeys-hook
- Published: 2025-04-01
- Live: https://snippix.vercel.app
- Repo: https://github.com/aayushbharti/snippix
- URL: https://aayushbharti.in/projects/snippix
## Why I Built This
I share code snippets on Twitter and LinkedIn regularly, and every tool I tried had the same problems — limited themes, no export control, or a clunky interface that made a 10-second task take a minute. I wanted something I'd actually enjoy using: fast, keyboard-driven, and visually sharp.
Snippix started as a weekend project and grew into a proper tool once I realized other developers had the same frustration.
---
---
## How It Works
You paste code, pick a theme and font, and Snippix generates a styled preview in real-time. **Highlight.js** handles syntax detection automatically — no need to manually select a language. The preview is fully customizable: font size, padding, background style, window controls, and line numbers.
When you're happy with the result, export as **PNG** or **SVG**, or copy directly to clipboard. The export uses **html-to-image** to capture the DOM node as a pixel-perfect image.
State management runs on **Zustand**. Every customization option — theme, font, padding, background — lives in a single store with selector-based subscriptions, so changing one setting doesn't re-render the entire app.
---
---
## Key Decisions
### Zustand for instant theme switching
Theme and font changes need to feel instant. React Context would re-render the entire tree on every change. Zustand's granular subscriptions mean only the preview panel and the active control re-render — the rest of the UI stays untouched.
### html-to-image over canvas-based rendering
I evaluated canvas-based screenshot libraries, but they struggled with CSS transforms, custom fonts, and z-index stacking. html-to-image captures the actual DOM, which means the export matches the preview exactly. The tradeoff is slightly larger file sizes, but accuracy matters more for this use case.
### Drag-to-resize with react-resizable-box
Rather than fixed width presets, I added drag handles so users can size their snippet to fit any context — a tweet, a blog post, or a slide deck. This was a small addition that significantly improved usability.
## What I Learned
**DOM-to-image is fragile.** Scroll offsets, transforms, and shadow DOM elements can all break the capture. I spent time isolating the preview node and ensuring no external CSS bled in during export.
**Defaults matter more than options.** My first version had too many controls visible at once. Reducing the initial UI to theme + font + export, with advanced options tucked behind a toggle, made the tool feel faster even though it has the same feature set.
**Keyboard shortcuts change the UX entirely.** Once I added hotkeys for the most common actions, my own workflow sped up dramatically. It's a small investment that signals to power users that the tool respects their time.
---
---
## Flux Lura
> A free online tool for seamless multimedia conversion. Transform images, audio, and videos effortlessly — elevate your content in seconds.
- Tech: nextjs, react, ffmpeg, typescript, shadcn-ui, tailwindcss, motion
- Published: 2025-01-01
- Live: https://fluxlura.vercel.app
- Repo: https://github.com/AayushBharti/Flux-Lura
- URL: https://aayushbharti.in/projects/flux-lura
## Why I Built This
Online media converters are either riddled with ads, require uploads to sketchy servers, or cap you at a handful of free conversions. I wanted a tool that runs entirely in the browser — no server uploads, no file size limits beyond what your machine can handle, and no dark patterns.
Building it also gave me an excuse to explore WebAssembly in a real-world context. Running FFmpeg in the browser is a fundamentally different challenge than calling it on a server.
---
---
## How It Works
You drop a file onto the page, choose your target format, and hit convert. The processing happens entirely client-side using **FFmpeg.wasm** — a WebAssembly build of FFmpeg that runs in the browser's sandbox. No file ever leaves your machine.
The app supports all major format conversions: MP4 to MP3, WebP to PNG, WAV to OGG, and dozens more. The UI shows real-time progress during conversion and provides a download link when complete.
The frontend is a Next.js app styled with Tailwind CSS and Shadcn UI. Motion.dev handles the transition animations between upload, processing, and download states.
---
---
## Key Decisions
### Client-side processing over server-side
The entire value proposition is privacy and speed. Uploading a 500MB video to a server, waiting for conversion, and downloading the result is slow and requires trust. Running FFmpeg locally eliminates both problems. The tradeoff is that conversion speed depends on the user's hardware, but for most common operations it's fast enough.
### FFmpeg.wasm and its constraints
The WebAssembly build of FFmpeg is powerful but has real limitations. Memory is constrained by the browser's sandbox, multi-threading support varies across browsers, and not every FFmpeg codec is available in the WASM build. I had to test extensively across browsers and document which conversions work reliably.
### Minimal UI for a complex operation
Media conversion has a lot of possible options — bitrate, codec, resolution, audio channels. I deliberately kept the interface simple: pick input, pick output, convert. Advanced users can dig into the repo, but for the 90% use case, the defaults work well.
---
---
## What I Learned
**WebAssembly memory management is manual.** Unlike server-side FFmpeg where the OS handles cleanup, the WASM version requires explicit memory allocation and deallocation. Failing to free buffers after conversion leads to crashes on large files.
**Browser APIs vary more than you'd expect.** SharedArrayBuffer (needed for multi-threaded FFmpeg) requires specific CORS headers and isn't available in all contexts. I had to implement fallbacks for single-threaded conversion in environments that don't support it.
**Simple UIs are harder to design.** Hiding complexity behind a clean interface requires more design thinking than exposing every option. Choosing the right defaults and knowing what to omit was the real challenge.
---
---
## aayushbharti.in
> A full-stack developer portfolio with a multi-format content pipeline, answer engine optimization, real auth, a real database, and analytics that survive ad blockers. One MDX file publishes to four channels — the site you're reading right now.
- Tech: nextjs, react, typescript, tailwindcss, postgresql, prisma, better_auth, mdx, zustand, zod, motion, posthog, resend, shadcn-ui
- Published: 2024-07-01
- Live: https://aayushbharti.in
- URL: https://aayushbharti.in/projects/aayushbharti
## Why I Built This
Most developer portfolios are brochures. They solve a presentation problem — make me look hireable — and stop there. I wanted to solve a distribution problem instead.
I write one MDX file. The site turns it into a rendered page, a plain Markdown endpoint for LLMs, an RSS feed entry, and a searchable text index. **One source, four formats.** Press publish, and humans reading Chrome, AI models ingesting plain text, crawlers indexing structured data, and feed readers polling RSS all get fresh content — from the same pipeline, in the same deploy.
Everything else exists to support that pipeline. OAuth so the guestbook works. PostgreSQL so entries persist. Resend so the contact form sends real emails. PostHog so I know what people actually read. None of it is decorative — every dependency earns its place.
---
---
## Architecture Overview
Three layers, deliberate boundaries.
**Content layer** — MDX files on disk, validated by Zod at build time, wrapped in React `cache()` for request-level deduplication. Every content route is statically generated — `revalidate = false`, `dynamicParams = false`. No runtime data fetching. The filesystem is the database.
**Application layer** — Next.js App Router with React 19 and the React Compiler. Server actions handle every mutation and return typed result objects instead of throwing — callers own their side effects. No middleware file; routing logic (social redirects, `.md` rewrites, PostHog proxy) lives entirely in `next.config.ts`. Environment variables validated at build time via `@t3-oss/env-nextjs` — empty strings coerce to undefined, missing secrets fail the build before anything ships.
**Infrastructure layer** — PostgreSQL via Prisma, better-auth for OAuth, Resend for transactional email, PostHog via first-party reverse proxy. All `/ingest/*` traffic routes through the app domain — no third-party requests, no ad blocker issues. Discord webhooks fire on form submissions and guestbook entries. Every external service fails silently: a Resend outage doesn't break guestbook submission, a Discord timeout doesn't block the contact form.
Client state is scoped to three Zustand stores (sign-in modal, contact drawer, guestbook with optimistic deletes) and a Cmd+K command palette that indexes every page at module load for instant fuzzy search.
```
app/
page.tsx — Homepage (hero, globe, projects, skills)
blog/
page.tsx — Blog listing with tag filtering
[slug]/page.tsx — MDX blog post
rss.xml/route.ts — RSS 2.0 feed
projects/
page.tsx — Projects listing
[slug]/page.tsx — MDX case study
guestbook/ — Auth-gated entries
api/
auth/[...all] — better-auth catch-all
md/ — Plain Markdown for LLM consumption
og/ — Dynamic OG image generation
llms.txt/ + llms-full.txt/ — LLM content indices
content/
blog/*.mdx — Blog posts
projects/*.mdx — Project case studies
experience/*.mdx — Work history
lib/
content/
mdx.ts — File loaders with gray-matter
schema.ts — Zod frontmatter schemas
collections.ts — Cached getters
toc.ts — Heading extraction
seo/
json-ld.ts — Structured data generators
metadata.ts — Metadata factory
site-metadata.ts — Site config
auth.ts — better-auth server config
prisma.ts — Singleton client with pg adapter
posthog.ts — Deferred loader
rate-limit.ts — In-memory sliding window
actions/
contact-form-actions.ts — Resend batch emails
guestbook-actions.ts — CRUD + Discord webhooks
spotify.ts — Now-playing with 3-tier fallback
```
---
## Content Pipeline
Every piece of content starts as an MDX file. gray-matter extracts frontmatter, Zod validates it against typed schemas, reading-time calculates duration, and `next-mdx-remote/rsc` renders the result with rehype-slug for heading anchors and Shiki for syntax highlighting. Custom MDX components — Callout, Section, Media, FileTree, Steps, CodeBlock, Accordion — extend what Markdown can express without leaving the authoring format.
**Single source, four formats:**
1. **HTML** — the rendered page with custom components and syntax highlighting.
2. **Plain Markdown** — JSX stripped via regex, served at `/{page}.md` URLs through Next.js rewrites. LLMs get clean Markdown without parsing HTML.
3. **RSS 2.0** — full-content feed at `/blog/rss.xml` with author metadata and category tags from frontmatter.
4. **LLM text indices** — `/llms.txt` returns a structured index with links; `/llms-full.txt` inlines every post and project body into one response.
The table of contents extracts h2/h3 headings, skips code blocks, and generates slugs via github-slugger. It renders as a sidebar that tracks the active heading through IntersectionObserver — scroll down, and the sidebar follows.
---
## Answer Engine Optimization
Search is shifting from links to AI-generated answers. If your content can't be parsed by an LLM, it doesn't exist in that world. So every page on this site speaks two languages: rich HTML for humans, clean plaintext for machines.
### Structured data
Every page emits JSON-LD via type-safe generators built on `schema-dts` — Person and WebSite on the root layout, Article on blog posts, CreativeWork on projects, BreadcrumbList on nested routes. The metadata factory sanitizes titles to 60 chars and descriptions to 155 chars at word boundaries. Google bot directives enable `max-snippet: -1`, `max-image-preview: large`, and `max-video-preview: -1` for rich snippet eligibility.
### Machine-readable endpoints
Every content page has a `.md` counterpart:
| Human URL | Machine URL |
|---|---|
| `/blog/some-post` | `/blog/some-post.md` |
| `/projects/some-project` | `/projects/some-project.md` |
| `/about` | `/about.md` |
These are Next.js rewrites to `/api/md/*` route handlers that strip JSX via regex — imports, self-closing components, block-level tags — and return `text/plain` with frontmatter metadata intact. No HTML parsing required. `/llms.txt` and `/llms-full.txt` provide bulk access, cached at 1hr client-side and 6hr at the edge.
### RSS
The feed at `/blog/rss.xml` generates standards-compliant RSS 2.0 with full content bodies — not excerpts — plus author metadata, category tags, and post images. Feed readers and AI aggregators that poll RSS get fresh content automatically.
### Traditional SEO
- **Dynamic sitemap** — per-type priorities (blog 0.7, projects 0.6, static 1.0), `published` flag filtering, canonical URLs on every page.
- **OG images** — dynamically generated at `/api/og` with type-specific layouts. Twitter cards get separate truncation limits because Twitter's preview parser is stricter than OpenGraph.
- **Security headers** — `X-Frame-Options`, `X-Content-Type-Options`, strict referrer policy, permissions policy disabling camera, mic, and geolocation.
- **Web manifest** — dynamic PWA metadata with theme colors and icons. Rewrite maps `/manifest.json` to `/manifest.webmanifest` for broad client compatibility.
- **robots.txt** — dynamic generation, points to the sitemap, allows all crawlers.
---
## Performance Engineering
The most expensive things on this site are GPU-bound: a WebGL globe, a shader background, canvas sparkles, and a carousel with autoplay. None of them run off-screen. Every one is gated by IntersectionObserver — mount once, observe always, animate only when visible.
- **3D globe** (`cobe`) — `useInView` with 200px margin. The `requestAnimationFrame` loop stops entirely when scrolled out. Spring-based pointer drag only calculates while visible.
- **Shader background** — speed drops to 0 when out of viewport. The GPU fragment shader stays compiled but does zero work.
- **Canvas sparkles** — raw `IntersectionObserver` (no library) pauses the RAF loop. Canvas stays mounted, draw cycle stops.
- **Embla carousel** — `useInView` with 100px margin controls autoplay. No transitions fire off-screen.
No rogue animation loops burning CPU in the background.
### Adaptive rendering
`usePerformanceMode()` reads three signals — core count (`<= 4`), viewport width (`< 768px`), and `prefers-reduced-motion` — and degrades GPU-heavy components accordingly. The shader disables, the globe simplifies. Debounced resize at 150ms keeps it responsive without thrashing.
### Load deferral
Nothing loads until it has to.
- **PostHog** — singleton with lazy `import()`. First user interaction triggers the download.
- **Vercel Analytics / SpeedInsights** — `next/dynamic` with SSR disabled.
- **Motion** — ships only `domAnimation` via `LazyMotion` (~15KB vs ~34KB).
- **React Compiler** — handles memoization at build time. Zero manual `useMemo` or `useCallback` in the entire codebase.
### Build-time optimizations
- **`inlineCss`** — eliminates render-blocking stylesheets in production.
- **`removeConsole`** — strips everything except `error`.
- **`optimizePackageImports`** — tree-shakes lucide-react, date-fns, motion, cobe, embla-carousel-react, and @paper-design/shaders-react.
- **Images** — served as AVIF/WebP with 1-year cache TTL.
---
## Backend Systems
Authentication runs through better-auth with GitHub and Google OAuth, backed by a Prisma adapter on PostgreSQL. A single catch-all route at `/api/auth/[...all]` handles every flow. On the client, `signIn`, `signOut`, and `useSession` export with full type inference. PostHog fires `auth_signed_in` with the provider on completion, and `identify()` ties analytics sessions to authenticated users.
The guestbook is the most complete end-to-end feature. A visitor signs in through the OAuth modal, writes a message (Zod-validated, 5-100 chars), hits a rate limit check (3 per 5 minutes via an in-memory sliding window), and the server action creates the Prisma record, sends a confirmation email through Resend, fires a Discord webhook, and revalidates the page — all in one server action. Deletion is author-only with a 5-second undo toast. Soft deletes via a `published` boolean keep the data intact, and `onDelete: SetNull` preserves entries even if the user account is removed.
The contact form follows the same pattern: Zod validation, rate limiting (3 per 15 minutes per IP), then `resend.batch.send()` fires two emails in a single API call — owner notification with IP and geolocation from Vercel headers, and a sender thank-you. Discord gets a webhook with a blue embed. Every external call is wrapped so failures never surface to the user.
---
## Key Decisions
### MDX over a headless CMS
No API latency, no vendor lock-in, no content/code drift. MDX gives React component embedding, git gives versioning, Zod gives schema validation. The tradeoff — non-technical editors can't contribute — is irrelevant for a personal site.
### better-auth over NextAuth
Prisma adapter that works with my schema out of the box, a clean plugin system, and full TypeScript inference from server to client. `nextCookies()` handles App Router edge cases transparently.
### Typed results over thrown errors
Server actions return result objects with a success/failure shape instead of throwing. Callers pattern-match and own their response — toasts, form resets, redirects. The type system enforces exhaustive handling. No try/catch chains, no error boundary gymnastics.
---
## What I Learned
**Content infrastructure outlasts content.** The MDX pipeline, AEO endpoints, and metadata factory pay dividends every time I publish. Write the file, and four formats update. That investment has already saved more time than it took to build.
**First-party analytics infrastructure isn't optional.** The PostHog reverse proxy doubled data collection overnight. Third-party domains get blocked by ad blockers, which means biased samples and phantom drop-offs. Routing through the app domain fixed that completely.
**Performance is a design constraint, not polish.** IntersectionObserver gating, adaptive rendering, and deferred loading shaped the component architecture from day one. Treating performance as a hard requirement — not a "nice to have" — forced better abstractions across the board.
**Auth is the simplest hard problem.** The OAuth flow is trivial. Session management across server components and client hooks, cookie handling in App Router, making sign-in feel instant while three redirects happen behind the scenes — that's where the real complexity lives.
---
---